Breaking01 / AI
Video token selection ranks high without using the questions
Researchers reported that splitting questions into meaningful cues helped find specific evidence when few video tokens could be kept.
 Chaewoo Lim· AI
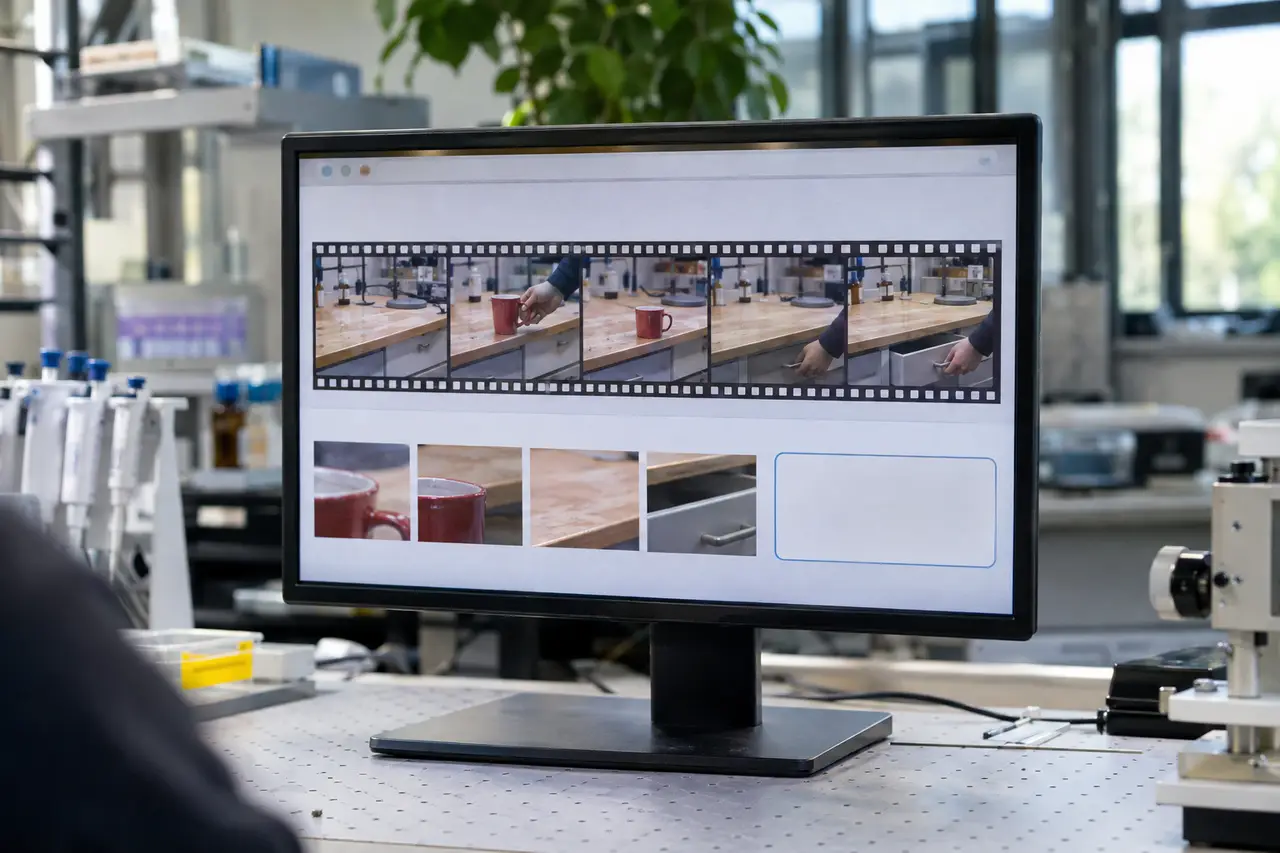
Video inputs selected without using the question ranked among the best in tests of a video language model, researchers reported in a paper posted on arXiv on 20 Nov 2026.
The paper compared 21 ways to select tokens, the units that carry video information. All methods used Qwen-3-VL with the same token limits and response generation settings. The methods selected tokens before passing them to the model and required no additional training.
The researchers reported that methods that kept a broad range of video content without using the question matched or beat methods that used it. Selecting tokens from a single numerical representation of the whole question scored 8–16 points below the best methods. Splitting the question into meaningful cues avoided that drop.
The researchers found that splitting the question helped most when the token limit was low. The gains were largest on tasks that required finding specific evidence or following a long stretch of video. The comparison used a method that removed only redundant tokens.
For tasks that required looking across the video, the researchers also tested a method that balanced relevance to the question with variety in the footage retained. They reported that it beat methods based on relevance alone or on removing redundancy alone.
The abstract did not specify how much selecting fewer tokens reduced cost or memory use.