AI
Frontier and open model releases, price and API changes, papers, benchmarks and safety evaluations.
VidToC compares video token compression across three tasks
The effects of video token compression varied by task, and the researchers also compared how the model’s underlying architecture mattered.
Last 7 daysNov 17 – Nov 22
Contrastive learning improves AI jailbreak detection
The method classifies new inputs by whether they are closer to a harmful or harmless prototype, without training a separate classifier.
SLAM-ASR relies on induction heads for speech transcription
Researchers found that some pairs of attention heads cancelled out noise in the attention signal and helped the model focus on the word it had just generated.
Weight transfers improve maths reasoning in language models
The researchers reported larger gains when the transferred layers overlapped more with the region linked to reasoning.
DOCK solves 15 robot object placement tasks in a simulation
The researchers trained DOCK using estimates of how far objects held by a robot gripper moved, based on the robot’s joint angles.
E-prop posts 100% survival in a humanoid robot walking trial
A learning rule modelled on biological nervous systems matched the survival rate of a non-biological baseline.
Stored abstracts lift ranking score in paper discovery test
KnowMe Paper Radar uses topic relevance and authors’ research histories to recommend papers and shows the evidence behind each part of the score.
Internal signals detect medical AI manipulation more often
Researchers ran the tests without retraining, using an existing tool to turn internal signals into text and a general-purpose model to evaluate it.
LUCID uses chest CT pretraining to correct cardiac PET scans
The model corrects signal loss in cardiac PET using maps made from the PET images, without a separate CT scan for each patient.
MORSEPose learns to estimate pose without surface models
The method uses labels for object pose and physical size to select observed points for surface reconstruction during training.
Speech recognition model tags breaths in transcripts
Xing-Audio-NVVASR led on mean composite score in benchmarks with human annotations, according to results published by the researchers.
AI model outputs first speech audio in 390 ms on NVIDIA GB10
A single model takes text, images and speech as inputs and uses a reference voice to synthesise speech.
Compressed translation models take up to 5.3 times as long
The study abstract reported lower memory use and changes of about one point or less in most aggregate translation scores. AI illustration
CaDO automates answer repair in causal reasoning datasets
The researchers turned plain-language questions into queries they could verify and compared how often each method changed answers that were already correct.
STAGE identifies causal links across disaster posts
Researchers reported that training STAGE on links between posts improved its performance more on wildfire posts than on Hurricane Harvey posts.
KIWI-EP cuts the time vLLM takes to generate an output token
KIWI-EP changes how tokens are sent to expert models and how the results are collected.AI illustrationJoint model detects more errors in first-person video
In the researchers’ evaluation, a model that jointly predicted which step was attempted, when it happened and how it went scored higher at detecting errors than a model that handled those tasks separately.
Models vary in reading context in English and Mandarin tests
Researchers reported that language models were more likely than human participants to take remarks literally in dialogue questions.
Single-pass model gets 46.0% on medical multiple-choice test
The researchers kept the language model fixed and trained only the part that compares questions with answer options.
Study tests language model weight repair without retraining
A fixed projection matched live selection closely on Pythia, while both procedures used the same family of operations in a separate test with a compound fault.
Arithmetic circuits go into model weights without retraining
A paper compared writing arithmetic rules directly into model weights with fine-tuning on examples.
IDWorld identifies people by body features without rendering
The model identifies people by predicting how their features would look in the same outfit, from a fixed angle or as a silhouette.
Longer histories improve forecasts of customer behaviour
The paper reported that extending the observation window improved forecast scores by more than the differences observed between sequence model families.
ReLay cuts model call costs in analogue circuit layout tasks
The researchers recovered code from existing circuit layouts and added recurring design procedures to a library of shared functions.
Image caching lowers word accuracy in Z-Image generation
The researchers reported that GuideCache restored how closely images followed prompts by recalculating only the parts with the largest predicted errors.
Reusing FAct improves image classification accuracy in tests
FAct ranked first in 11 of 16 test settings when training settings were tuned separately for each activation function.
TuringPAI-Drive generates in-vehicle driving paths at 12 Hz
The paper said TuringPAI-Drive ran in the vehicle on a single NVIDIA Orin-X chip.AI illustrationNew rule cuts false safety approvals in gallbladder surgery
The new rule cut false approvals in videos where experts disagreed, but also approved fewer videos on time when they met the safety standard.
Structured records flag the same missing results as answers
The author drew no conclusion about the effect of adding a record after the evaluator fell short of a pre-set human validation standard on the key category.
Qwen3-VL 32B varies simulated gaze with a basic prompt alone
Researchers reported that asking the model to describe where a user would look before simulating gaze made the results sensitive to changes in profile traits unrelated to gaze.
TETHER maps long documents from their tables of contents
TETHER matches text blocks to table of contents entries to find where chapters and sections begin and end, without additional training.
TRAC speeds up diffusion translation by adapting text length
In the researchers’ tests, TRAC reduced model calls and lowered the macro-average COMET translation quality score by 0.02 points.
AI bug reproduction is linked to more valid software reports
Researchers found that bug reports were more likely to be valid when AI helped reproduce or diagnose the error.
RoCoKV speeds up reasoning in a test against a full KV cache
Researchers designed RoCoKV to vary how much it compresses the KV cache according to the model’s confidence during inference.AI illustrationA logo changes AI responses to visible and infrared images
Researchers measured how often the same target response ranked first for both visible-light and infrared images.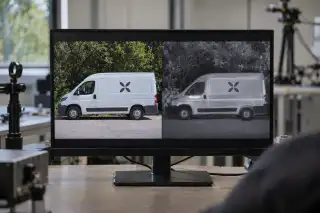
AI reads mammograms better by comparing images of both sides
The public abstract does not say how much diagnostic performance improved.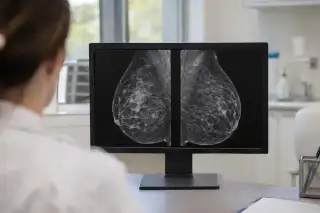
AI agents build retrieval-augmented generation from scratch
The combination that led the benchmark without starter code also improved human-designed systems in a separate experiment.
AI calorie estimates fail to scale with stated food weights
Multiplying each model’s calorie estimate per unit of weight by the stated food weight reduced errors for small and large portions.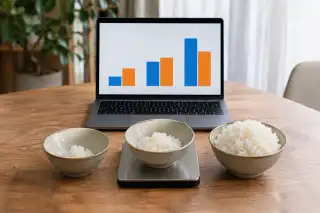
Review urges reasoning audits for medical AI certification
The authors said tests focused on correct answers can miss faulty causal reasoning.
Video token selection ranks high without using the questions
Researchers reported that splitting questions into meaningful cues helped find specific evidence when few video tokens could be kept.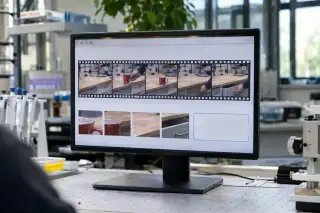
4-bit method cuts reasoning costs in a vision-language model
The researchers designed QL-VLM to preserve how a model retrieves information from images and text and to keep its reasoning aligned with the full-precision model.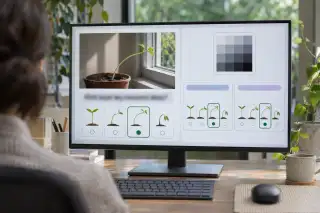
Algorithm lifts program accuracy by up to 22 points
An algorithm that selects input-output examples improved program induction accuracy over an agent using only a language model.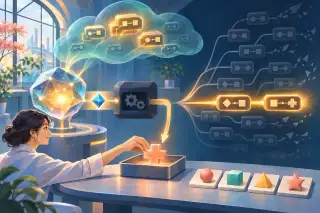
AG-JEPA improves early cognitive impairment classification
Researchers reported that learning features of specific brain regions improved diagnosis and disease progression prediction.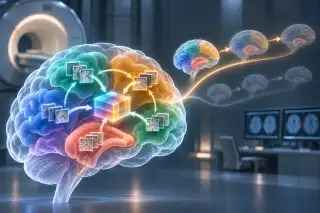
Study compares voice AI for Spanish freight negotiations
The study compared errors in recognising spoken amounts and response delays measured from the listener's side.
WebArena-Pro evaluates audio and video web agents
Codex and Claude Code share the highest reported score, each paired with a different model.
CTF-Dojo offers 658 tasks for language model training
CTF-Dojo provides verifiable execution results for agent training, while its published performance comparisons concern CTF security challenges.
FlashREINFORCE trains agents with one run per input
FlashREINFORCE researchers said their method reduced repeated runs per input while maintaining training stability.
Translation compression quality depends on the metric
A translation model compression study found disagreement between automatic metrics and used candidate reranking to improve both compressed systems.
CoT2Graph improves prediction of correct AI answers
Researchers linked correct reasoning to early planning and failed reasoning to overloaded synthesis steps and broken dependencies.
Phone prescription reader reports 67% medication recall
A study using the same prescription photographs reported fewer missed medications but longer processing times.
CECAR speeds on-device inference through expert selection
CECAR adds predictions of expert reuse to cache-aware routing for on-device inference.
Dunamu papers gain main conference and workshop acceptance
The acceptance routes identify where the research will be presented; assessing performance requires each paper's experimental conditions.
Spatial reasoning gains show limited generalisation
Researchers reported gains from spatial training questions alongside limits that varied by model.
Language model edits depend on evaluation conditions
Papers on refusal removal and vocabulary trimming assessed model behaviour after edits alongside the conditions used to evaluate it.
CivilBench exposes limits in AI numerical reasoning
The researchers said numerical priors and external knowledge helped only to the extent that models could interpret and use the evidence.
EEGProbe finds an alignment bottleneck in vision models
EEGProbe tests whether vision-language models need brain signals to answer questions and can connect those signals with other forms of information.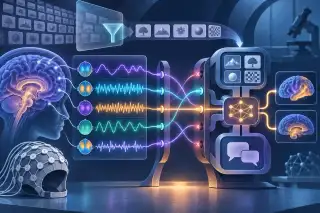
BLiMP-RO links training data to Romanian grammar scores
BabyBabelLM generally outperforms video captions at matched training sizes in the reported tests; the abstract reports no independent replication.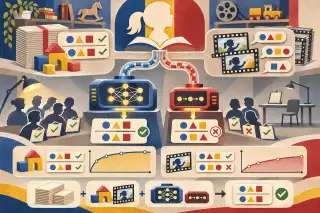
SceneAgent separates scene-building knowledge from engines
SceneAgent separates reusable scene-building guidance from engine integration, making execution cost part of the case for reuse.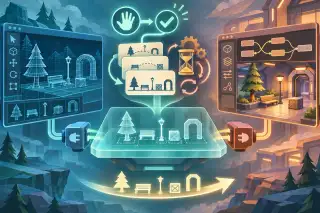
AI-written code improves unsolved scheduling benchmark
AI-written code achieved a smaller gap to the theoretical lower bound than commercial tools in a comparison using the same hardware and execution budget.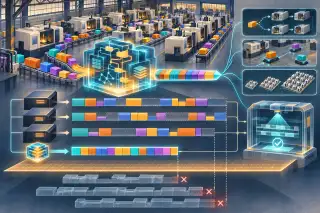
Forecast benchmark tests text that conflicts with trends
The study examined when text that contradicted historical trends increased forecast errors and how limiting forecast adjustments helped.
Lens tests satellite search without target-specific training
Lens searches image features with reduced positional bias and reports performance at the best threshold for each land-cover class.AI illustrationFEND aims to identify who answers voice AI calls
The proposed framework distinguishes people, voicemail, automated phone menus and AI to help voice agents choose how to respond.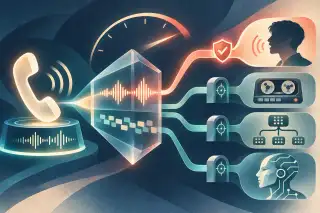
STaG adapts person search without new human descriptions
The proposed method uses descriptions from an existing environment and images from a new one to address text alignment and visual differences.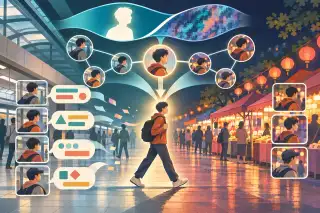
PERFARENA evaluates the cost of running AI-generated code
The open-source tool assesses code correctness alongside runtime, memory use and energy consumption.AI illustrationRAWATTA processes 200 images without additional training
The method uses 8-bit precision for attention calculations and retains 16-bit precision only in layers that require it after a calibration check.
Unfinished medical AI reasoning yields existing diagnoses
Researchers separated diagnoses already present in reasoning from answer completion and diagnostic correctness.AI illustrationAI proposes excess experiments in mineral exploration test
Researchers reported high recall but low precision when AI selected experiments to test geological hypotheses.
LLM evaluation framework looks beyond task scores
Researchers proposed a framework to assess how language models process knowledge recall and reasoning tasks.
AI-Voyager aims to help citizens revise AI rules
The proposed system links answers to government documents, but study participants rarely followed citations to check the source.AI illustrationSmall model decisions remain sensitive to who takes part
Pooling evaluations left participant effects intact, prompting researchers to recommend candidate sets and margins over forced rankings.
1 week agoNov 10 – Nov 16
Seoul National University AI cuts remote calls by 43.3%
The reported approach combines sensor control with AI inference to reduce calls to remote models.
Metal Sandbox raises Mac command throughput in tests
Metal Sandbox’s command throughput tests and session-based estimates used different conditions.
Satellite image vectors predict event completion dates
Researchers report using differences between satellite image vectors to collect event data without manual labelling and train a prediction model.
CineMME reveals gaps in linking dialogue to speakers
Researchers found that visual information helped some video questions but could hinder dialogue-based reasoning.
AI-favoured words rise 29% on least-edited sites
A study linked vocabulary growth to how often answers were edited, but did not observe actual model use.TFC-MMFD posts 99.40% accuracy in bearing fault diagnosis
The researchers evaluated the model on public datasets covering varied operating conditions, but the abstract disclosed no validation results from industrial equipment.
ThermalSplat rebuilds 3D scenes without camera positions
The method reconstructs new scenes from thermal images without colour guidance or additional training for each scene, according to the paper.Evaluation methods reverse image AI model rankings
Similar overall scores masked disagreement over individual images, while automated model rankings differed from human assessments.ChJGBench tests AI generation of Chinese court judgments
Researchers reported that legal models' strengths over general-purpose models varied by evaluation category.MITRA-Swarm lifts Sanskrit translation score by 0.63 points
The researchers reported roughly nine times the inference cost per verse compared with a single model.GPU-CPU method improves optimisation scores by up to 4.9%
The method passes GPU-calculated variable values to CPU solvers without training data or a pretrained model.Sophon tuning improves spatial reasoning in open models
Researchers traced spatial reasoning failures to a bottleneck in how models route information into answers.
MIGRO retains 99.9% of rebuilding quality after model switch
Researchers designed MIGRO to separate memory from individual language models so successive models can read and extend existing records.MemCrafter refines AI video prompts to aid memorability
Researchers proposed a method that repeatedly revises video generation prompts using estimated neural responses to predict memorability.
Weight deletion delivers gains on par with full fine-tuning
Researchers reported lower storage needs for training results alongside preserved existing abilities.Image segmentation method finds look-alikes without training
The method finds candidate objects, compares them with a reference image and outlines the matching object.AFTER-WM adapts robot predictions without changing models
Researchers proposed combining short-lived and lasting corrections to adapt robot motion predictions while keeping pre-trained models unchanged.
FreeDeshadow targets shadows cast by selected objects
The framework lets users select an object with a dot, line, mask or text to remove only the shadow it casts.PhysICL predicts physical fields without retraining
PhysICL uses simulation examples to predict physical quantities across a new mesh while keeping its model weights fixed.PREWARN separates failure detection from early warning
Researchers said detectors with similar response classification scores differed in their ability to warn before a language model failure began.Classifier outperforms model at detecting perturbations
Researchers cautioned that identifying a perturbation's location does not imply broad access to a model's internal computation.TKNP raises long-context AI throughput by up to 1.7 times
Splitting a model across servers while keeping each request's attention on its assigned server is central to TKNP's throughput comparison.
AVCC adds human benchmark for next-speaker prediction
The benchmark compares human and model predictions on the same conversation samples recorded with a single camera and microphone.
Alania-2 lowers word error rate in Turkish speech synthesis
The paper also reported results from a text normaliser that spells out numbers and names as Turkish speakers would pronounce them.
B3 speeds up self-editing diffusion language models
The method needs no additional training or parameter tuning, and researchers reported generation quality on par with the base model.
Emotional headlines raise AI severity ratings
Providing the article body reduced the effect of headline wording on AI severity ratings, the paper reported.
AI video detectors miss most fakes after reposting
Researchers identified changes in generators and content, alongside repost compression, as separate causes of weaker detection.Drone disaster model uses 0.1 MB of storage
The picoEmergencyNet researchers presented a design tailored to disaster classification instead of increasing model size.
AI benchmark tests nonverbal reasoning in early childhood
Researchers reported that vision-language models recognised context well but struggled to interpret specific behavioural and interpersonal cues.
Synthetic emissions scenarios cut climate AI training runs
Training on extreme emissions changes could reduce simulation runs, but that claim needs to be assessed separately from prediction quality.
LIS claims safety alignment gains with a smaller dataset
The researchers address safety and unnecessary refusals together, but the abstract omits evaluation model names and benchmark-specific scores.
Multi-word training cuts English tokens; model tests remain
Researchers reported compression gains but did not evaluate models trained with the new tokenizers.
Legal AI training method balances reasoning and answers
The method balances learning from reasoning and final answers, then adjusts auxiliary rewards according to their effect on the final evaluation.
Language gaps persist in document understanding benchmark
Researchers reported that larger models did not narrow performance gaps between languages in the MDU benchmark.
AI research forecasts broaden beyond company insiders
External researchers joined company insiders in forecasting rapid AI progress, but the forecasts concern when research capabilities might emerge.
CaseScope finds instability in AI pathology diagnoses
Open models were more affected by specimen-site information than by additional images on teaching cases, the researchers reported.
Place search accuracy falls when source views change
AcrossPlace researchers report lower place-search accuracy when retrieval images differ from those used to generate descriptions.
MICRO benchmark pairs retinal images across surgery phases
Researchers proposed a one-step learning method that aligns retinal images using similarities in their blood vessel structures.PolyRoute sets benchmark for routing queries in 12 languages
All test messages and answers are AI-generated, while a statistical classifier scores 91.9% in the researchers’ published results.FERN improves table retrieval without generative AI
FERN reported gains from reranking on Spider, but its Fiben comparison used different question sets.Safety score calibration cuts harmful responses in VLM test
Researchers report fewer harmful responses after training a vision-language model with calibrated scores and limits on harmful assistance and unnecessary refusals.
HintErase targets subtitle removal despite detection errors
The model uses the original video and region hints to remove missed subtitles while preserving wrongly marked background.
AI video ad review framework gives humans the final say
Reviewers accept or reject model findings and send confirmed problems to matching editing tools.
FoleyForge proposes sound editing that preserves identity
The design combines a training pipeline that creates editing examples with controls for loudness and edit strength.
E2VID yields 40 person detections in reconstruction test
Researchers reported a detection gap between reconstructed images and direct representations even in a retrospective comparison that capped background false positives.PASE separates agent skill procedures into editable code
The framework moves reusable procedures into executable programs to reduce repeated revisions to natural-language skill documents.Natural safety responses improve retention after training
Researchers propose NEST, a training approach that uses context-aware safety responses instead of formulaic refusals.LEMMO extends signal analysis to detailed descriptions
The study broadens evaluation from signal classification to factual descriptions, with gains measured against comparisons published by the researchers.Spacecraft AI memory scores differ after session restart
AstroMemBench researchers reported no clear advantage for memory systems over retrieval-augmented generation within the same session.ICLayout-Bench scores only circuit layouts that pass checks
A paper evaluating electrical performance and area reported substantial differences in model costs between configurations with similar scores.
Physics2Weight generates neural weights from physical laws
The study reports lower solution errors than conventional physics-informed neural networks, alongside limits in satisfying physical laws for nonlinear equations.AI validation filters out harder language-model test items
Researchers said AI validation removed questions whose answers humans supported, raising language models' benchmark accuracy.TimeOmni-o1 links language reasoning to forecasts
The researchers presented a two-way architecture that feeds language-model reasoning into time-series forecasting.
Real-time maths checks improve reported reasoning accuracy
A preprint reports higher symbolic maths accuracy alongside increased token use, while its abstract reports no independent replication.KAIST targets data management bottleneck in flash storage
The reported improvement focuses on moving and reorganising data so storage space can be reused.
OmniReview offers benchmark for reviewer recommendations
Researcher profiles and staged evaluation aim to reflect real editorial workflows.Medical AI shows gap between recall and evidence use
A Chinese-language benchmark reported lower scores for matching evidence and formulating recommendations than for identifying clinical information.Pinterest uses GLOC to share labels across image groups
Researchers reported better search quality and efficiency by generating descriptions for groups of similar images.
Scientific code AI routes repairs by failure type
Targeted repairs and separate verification put token use and translation correctness under the same evaluation.
Hybrid AI lacks evidence for 13.6% of police video events
Researchers reported speaker attribution errors and poorer performance across all tested systems on edited footage, long recordings and noisy audio.
SPECTRA proposes restoring model refusals without retraining
Researchers report that transferring a base model’s refusal direction improves safety while preserving specialist knowledge.MapHub reports results for personalised paper selection
The authors report paper-selection results from their own blind ratings, while the abstract reports no independent replication.TeViD compares two approaches to Turkish video fact-checking
TeViD combines fact-checking articles, translated material and synthetic examples to compare evidence retrieval with a fine-tuned model.
JCMC proposes controls for persistent language model memory
The design checks predicted memory effects against observed results, but the paper reports no performance comparison with simpler retrieval methods.Translation AI favours new meanings despite ignore orders
A controlled Mandarin-to-English experiment found that reliance on supplied word meanings varied with word frequency and sentence context.Google DeepMind uses AI to verify Signal's core code
Google DeepMind said AI agents proved that executable code met security conditions reviewed by experts, with Lean checking each proof.
JevGPT links evidence review with research planning
The dual-system design connects evidence processing to research planning, but the abstract gives no performance scores or costs for individual comparators.AI misinformation costs 3–169 times less to make than check
VEX-Bench assesses the burden of checking AI-generated misinformation across several dimensions.AI manufacturing models can run yet give wrong answers
Comparison with reference models exposed errors in the researchers' evaluation; the abstract reports no independent replication.
DramaGrow reports accuracy gap between AI judging methods
The preprint compares repeated scoring with direct pairwise comparison and reports that evaluation procedures affect the accuracy of AI drama judges.Study raises video AI object-counting accuracy to 65.0%
The paper reports improved counting in synthetic videos alongside limits in real-video evaluation.Linear merging lifts Turkish model's maths score to 0.63
Researchers reported that data quality mattered more than training volume in fine-tuning.MCGI adjusts vector search effort to data geometry
MCGI uses distances calculated during search to adjust search effort, with performance measured against DiskANN on the same index.Extra layers give mixed gains in Vietnamese punctuation test
The preprint fixes training at eight epochs and does not report how rankings shift once architecture-specific tuning is added.RoleWalk embeds one million graph nodes on a single CPU core
The question for training-free structural embeddings is less speed than whether coordinates hold across different graphs.Multilingual MARS agent trades retrievers for shell commands
The authors said MARS beat existing methods, but the abstract gives neither the accuracy gap nor the number of languages tested.
Anthropic and Claude finish first vault 3D model in 34 hours
Anthropic's biology team reached an initial 3D model of a new vault particle form in 34 hours rather than weeks, AI Times reported, pointing to possible AI support in fields where scientists lack specialist experience.A YOLO extension reads runway lines for vision-based landing
The design backs up keypoints, which are prone to occlusion, with straight lines, but the abstract reports no real flight-test results.Skill at editing AI weights concentrates in a few new models
A structured-response task resisted every attempt, and success in one task family correlated poorly with success in others.GeoJeV trades 1.12 extra seconds for 5.32 points of accuracy
GeoJeV steers image search with probability distributions instead of generated text, but the abstract does not name the method behind its 7.8-fold speed comparison.MINE lifts Llama 3.1 8B inference speed 2.52x on RTX 4060 Ti
The researchers' figures come from a 2.1-bit EntQuant checkpoint of Llama 3.1 8B Instruct, and the speedup was 1.48 times on an RTX 5090.Khmer benchmark drops LLM judges but still needs LLM answers
The judge is gone from scoring, but LLMs still write the reference answers and the human check is one native speaker's ratings.Soongsil decoy servers block ARTEX AI tool in 60-server test
The test opponent was a tool disclosed as used in state-backed hacking, and public materials show no deployment on live production servers.
Peer signals reduce LLM public accuracy by up to 47.8 points
The researchers wrote that multi-agent evaluations must measure whether agreement reflects private judgments, not only whether models reach it.Denoising audio before speaker embeddings raises error rates
The paper advises leaving input audio untouched and shrinking only the output vector, but its abstract gives no per-model error ratesShapley benchmark finds standard metrics differ on real data
The authors said standard metrics picked contradictory best methods on real data and that the way inputs are grouped mattered more than the choice of imputer.20 Atari games expose vision AI's limits in following motion
The latest vision-language models often missed object motion and leaned on written history over new screens, a study found.ML benchmark for chaotic three-body orbits publishes dataset
Stability prediction and long-horizon trajectory prediction differed in difficulty, the researchers wrote; the abstract gives no accuracy gaps between modelsKLEAR holds knowledge fixed to test Korean LLMs' application
The design aims to separate the causes of wrong answers that accuracy scores conceal, though the abstract names no evaluated models and gives no scores.2 weeks agoNov 03 – Nov 05
Drex Max decision model scores 67.52 on Decision Index 0.4.1
The score and response times of the open model, which returns only a probability for each option, are the authors' own figures and have no independent replication.Apple's KeyNet cuts RAG search time by up to roughly 8 times
The research learns query patterns in advance to cut RAG search costs, and Apple's post does not give the pre-training time.
Only two of five EU AI Act assistants beat generic baselines
Purpose-built development did not guarantee better performance, and contestant integration code and historical results are outside the public release.3 weeks agoOct 29
AI agents' experiment ideas clear review in 194 of 415 cases
Evidence that agents' own rankings help decide which experiments to run first is still limited.Oct 2026Oct 12 – Oct 25
Meta researchers release 120-task test for wearable AI aides
The benchmark scores the final state of a virtual world rather than written answers, but the repository notes list no pass rates by model.
Auditable AI text detector reports small drop in performance
The authors say the detector must not be used for decisions about individuals and that its accuracy beyond its training scope is not established.
Anthropic seeks life scientists for 8–12 week Claude studies
Anthropic covers the cost of running its models and researchers keep their data rights, but the company has not disclosed how many applicants it will select.
EGI-BENCH puts eight enterprise agent benchmarks in one tool
The authors report that no model leads on every capability axis, but the abstract gives no deep-mode scores.Apple's SSR cuts per-turn reasoning latency by more than 90%
The framework replaces freeform reasoning with a choice among preset candidates to reduce inference costs in small models, and Apple has not disclosed any product plans.
Mixing English in pre-training matches 2–13× the Arabic data
Mixing in another language improved pre-training for data-poor languages more than adjusting settings did, the Apple paper said.
Apple's Minions pools idle Mac GPUs into a virtual GPU cloud
An Apple research paper turns GPUs that normally sit idle into inference capacity, targeting the cost and wait times of centralised infrastructure.
Apple paper tests LLMs against humans on translation scoring
The paper argues that LLMs need thorough evaluation across language pairs and domains before they replace human evaluation of translations.
171 in totalWritten by Gyeol HanRSS feed