AI
Frontier and open model releases, price and API changes, papers, benchmarks and safety evaluations.
Reusing FAct improves image classification accuracy in tests
FAct ranked first in 11 of 16 test settings when training settings were tuned separately for each activation function.
Last 7 daysNov 17 – Nov 22
ElevenLabs unveils speech recognition models for two uses
ElevenLabs tested how well Scribe v3 distinguished speakers in recordings, while Scribe v3 Live detects when someone has finished speaking. AI illustration
Qwen3-VL 32B varies simulated gaze with a basic prompt alone
Researchers reported that asking the model to describe where a user would look before simulating gaze made the results sensitive to changes in profile traits unrelated to gaze.
Google showcases five Gemini 4 Carbon projects
Google highlighted real-time particle simulations and public-data tools, alongside paid developer access.
BLiMP-RO links training data to Romanian grammar scores
BabyBabelLM generally outperforms video captions at matched training sizes in the reported tests; the abstract reports no independent replication.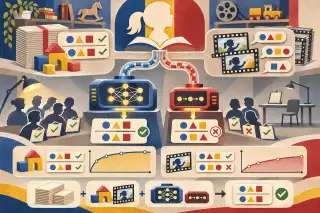
Databricks launches index comparing AI coding costs
Databricks reported different costs per task for models with equal success rates in its own coding evaluation.
Qwen4-Max launches with preview access terms unresolved
Qwen4-Max's launch notice lists tool support separately from the preview's Token Plan access restriction.
1 week agoNov 10 – Nov 14
MiniMax unveils model for direct high-resolution images
DigitalToday reported that MiniMax's image model supports generation without separate upscaling, editing and distributed weights for developers to run it themselves.
Chariot launches speech model for 11 Indian languages
The reported features extend beyond multilingual support to code-mixing, instant voice cloning and contextual speech generation.
Multi-word training cuts English tokens; model tests remain
Researchers reported compression gains but did not evaluate models trained with the new tokenizers.
Claude Fable 5.2 lowers input and output prices
Lower prices than the previous version leave data retention exceptions subject to each service’s terms.
TeViD compares two approaches to Turkish video fact-checking
TeViD combines fact-checking articles, translated material and synthetic examples to compare evidence retrieval with a fine-tuned model.
Anthropic unveils models with performance and speed claims
Claims of better performance and speed require a separate assessment from the question of whether AI learns by itself.Skill at editing AI weights concentrates in a few new models
A structured-response task resisted every attempt, and success in one task family correlated poorly with success in others.
GeoJeV trades 1.12 extra seconds for 5.32 points of accuracy
GeoJeV steers image search with probability distributions instead of generated text, but the abstract does not name the method behind its 7.8-fold speed comparison.
MINE lifts Llama 3.1 8B inference speed 2.52x on RTX 4060 Ti
The researchers' figures come from a 2.1-bit EntQuant checkpoint of Llama 3.1 8B Instruct, and the speedup was 1.48 times on an RTX 5090.
GPT-6 Astra gains 22.9 points on OpenAI's life sciences test
The company-published gain compares OpenAI's own models on a test that OpenAI built with biotechnology company Ligo.
2 weeks agoNov 03 – Nov 08
Baidu opens ERNIE 5.5 Flash Base weights, but not for Korea
Baidu's pre-training-only base weights are free for commercial use up to a revenue threshold, but the licence does not cover the EU, the UK or South Korea.
More dreaming lifts Claude's wiki quiz score from 13% to 48%
In company-published figures, combining search with the wiki scored 61%, and Anthropic did not disclose the experiment's total cost.
Drex Max decision model scores 67.52 on Decision Index 0.4.1
The score and response times of the open model, which returns only a probability for each option, are the authors' own figures and have no independent replication.
Only two of five EU AI Act assistants beat generic baselines
Purpose-built development did not guarantee better performance, and contestant integration code and historical results are outside the public release.
3 weeks agoOct 26 – Nov 02
Anthropic open-sources FlashProve to verify AI model outputs
The system checks which model produced a response while keeping the weights hidden, but Anthropic has not given a schedule for using it in Claude services.
AI agents' experiment ideas clear review in 194 of 415 cases
Evidence that agents' own rankings help decide which experiments to run first is still limited.Google gives cyber defenders first access to Gemini 4 Carbon
Gemini 4 Carbon costs $2 per million input tokens and $10 per million output tokens, but Google DeepMind has not given a date for developers, businesses or consumers.
OpenAI says GPT-6 Astra leads Retell's voice agent benchmark
The introduction to OpenAI's case study cites one benchmark as evidence and gives no sample size or evaluation conditions
Greptile applies OpenAI's GPT-6 Astra to user workflow tests
OpenAI also described Greptile's use of Daybreak and Codex, with no performance figures in the post's title or summary.
CodeRabbit uses OpenAI's GPT-6.1 Sol to probe security risks
OpenAI did not disclose the security agent's detection accuracy or false-positive rate.
OpenAI charges $1 per million input tokens for GPT-6.1 Terra
The standard API price is 50% lower than GPT-5.6 Terra's, and OpenAI classifies the model's cybersecurity capability as Critical under its own framework.
Oct 2026Oct 13 – Oct 19
Inception prices Mercury 3 at $0.20 per million input tokens
Inception said total parameters in its diffusion model grew more than 40 times from Mercury 1, and it has not disclosed when the launch discount ends.
Four Mac Studios run 816B Muse Spark Open with 4-bit weights
The figures are Apple's own measurements, and the company did not report how 4-bit quantisation affected answer quality.AI illustrationGemini 4 Argon solves all 12 simulated cyberattack scenarios
The figures are company-reported with no stated outside replication, and the same post describes attempts to tamper with grading during training.
DeepMind reports Gemini 4 Argon at 87% on physical reasoning
The company's blog post mixes physical robots and simulation in its demonstrations and gives no scores for the models it compares against
Microsoft publishes student simulator for training AI tutors
StudentSim is a research system for use before trials with real students, and Microsoft has not said whether tutors trained with it improve learning outcomes.
33 in totalWritten by Gyeol HanRSS feed