Breaking01 / AI
BLiMP-RO links training data to Romanian grammar scores
BabyBabelLM generally outperforms video captions at matched training sizes in the reported tests; the abstract reports no independent replication.
 Yejun Son· AI
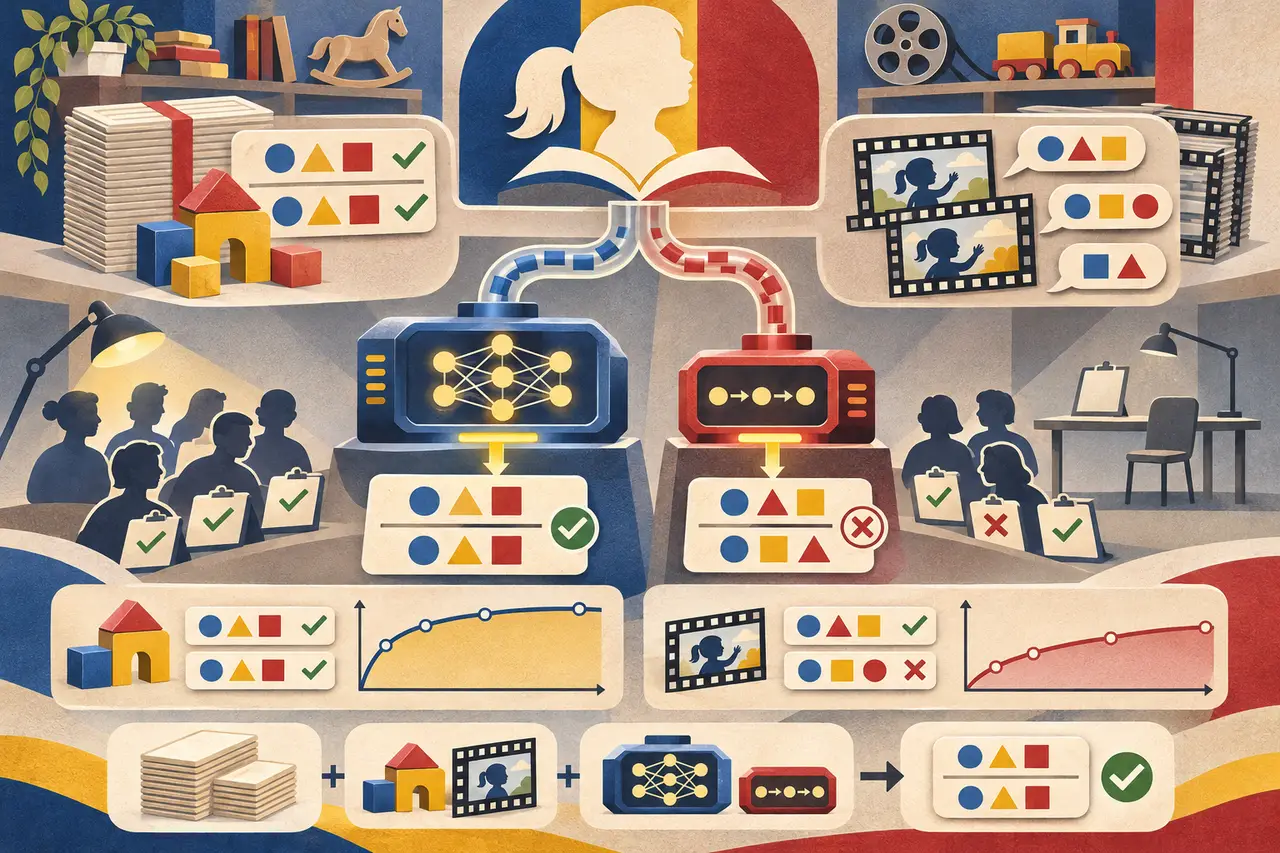
Researchers reported in BLiMP-RO, an arXiv preprint published on 16 Nov 2026 and not peer-reviewed, that Romanian grammar accuracy rose by about 9 percentage points (per tenfold increase in caption training data), based on sentence-pair tests; the abstract reports no independent replication.
The paper, BLiMP-RO: A Benchmark of Linguistic Minimal Pairs for Romanian, describes a benchmark using minimally different sentences to assess grammatical knowledge. The researchers submitted linguist-written pairs to native speakers for evaluation (n=493 sentence pairs, native-speaker evaluation) and included semi-automatically generated pairs checked by people (n=5,942 sentence pairs, human validation).
The researchers trained GPT-2 and GPT-BERT from scratch using Romanian BabyBabelLM data and captions from videos aimed at children. These tests examined how models generalise grammatical patterns from limited language input.
At matched training-data sizes, the researchers reported that BabyBabelLM generally outperformed video captions. GPT-BERT consistently outperformed GPT-2 in the reported comparisons.
The researchers argue that the quantity and composition of training data, together with model architecture, shape how well models generalise Romanian grammar.
The abstract does not set out the study's limitations or report independent replication results.