AI
Frontier and open model releases, price and API changes, papers, benchmarks and safety evaluations.
Phosphene introduces Music Studio for editing finished songs
Music Studio uses finished songs to create new performances and build music videos around their vocals and beat.
Last 7 daysNov 16 – Nov 22
Higgsfield compares 8-second clips made from a single prompt
Higgsfield judged Seedance 2.5 the closest match to its prompt after running each generation option once.
Thinking Machines Lab releases Inkling 2 Mini weights
Inkling 2 Mini runs its middle layers three times for every output token it generates. AI illustration
VidToC compares video token compression across three tasks
The effects of video token compression varied by task, and the researchers also compared how the model’s underlying architecture mattered.
Contrastive learning improves AI jailbreak detection
The method classifies new inputs by whether they are closer to a harmful or harmless prototype, without training a separate classifier.
SLAM-ASR relies on induction heads for speech transcription
Researchers found that some pairs of attention heads cancelled out noise in the attention signal and helped the model focus on the word it had just generated.
ElevenLabs announces plan to acquire Kotoba Technologies
The deal brings together two voice AI companies, and users have yet to learn which services will use Kotoba’s technology.AI illustrationWeight transfers improve maths reasoning in language models
The researchers reported larger gains when the transferred layers overlapped more with the region linked to reasoning.
AI content panel examines how creators decide what to show
Editorial judgement shapes what creators show, while dubbing tools change the language of a video's voice-over.
DOCK solves 15 robot object placement tasks in a simulation
The researchers trained DOCK using estimates of how far objects held by a robot gripper moved, based on the robot’s joint angles.
E-prop posts 100% survival in a humanoid robot walking trial
A learning rule modelled on biological nervous systems matched the survival rate of a non-biological baseline.
Ubisoft sets up Motherbrain as a generative AI games studio
Motherbrain’s projects include game characters with memory and an AI game master.
XYZ unveils a system that retrains robots on failed tasks
The system uses fresh demonstrations of tasks the robot failed to perform to guide its next round of training.AI illustrationStored abstracts lift ranking score in paper discovery test
KnowMe Paper Radar uses topic relevance and authors’ research histories to recommend papers and shows the evidence behind each part of the score.
Amazon Polly makes voice cloning available to select clients
AWS lets Amazon Polly customers create cloned voices for free and charges by usage when those voices turn text into speech.
AI guide recreates a husky dance from a single pet photo
The guide shows how to make the pet in a photo copy the husky’s dance, from the first lift of its front paws to the final pose.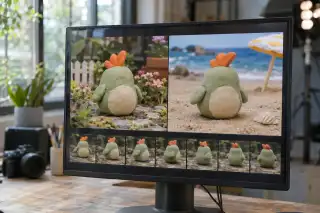
DocScan pulls measurements for tile roof estimates from PDFs
DocScan’s developers said PDF reports differ by supplier in how they lay out measurements and which units they use.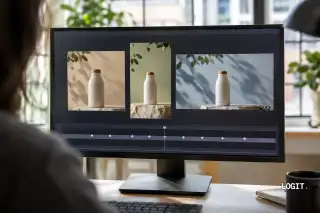
OpenAI prices voice API standby time at $0.02 per minute
The voice model can pause while a call stays connected, and the API bills follow-on model and tool use separately.
Internal signals detect medical AI manipulation more often
Researchers ran the tests without retraining, using an existing tool to turn internal signals into text and a general-purpose model to evaluate it.
Anthropic IPO and private placement total $119.5 billion
The IPO proceeds included shares sold by Anthropic and by existing shareholders.
Kakao founder Kim Beom-su is acquitted again on appeal
Before the ruling, Kakao announced additional funding for KakaoAI and revised the timetable for its corporate split.
Douzone Bizon unveils AI agent for public agencies
The company said the agent processes data on each agency’s internal network without sending it outside the agency.AI illustrationLUCID uses chest CT pretraining to correct cardiac PET scans
The model corrects signal loss in cardiac PET using maps made from the PET images, without a separate CT scan for each patient.
MORSEPose learns to estimate pose without surface models
The method uses labels for object pose and physical size to select observed points for surface reconstruction during training.
Speech recognition model tags breaths in transcripts
Xing-Audio-NVVASR led on mean composite score in benchmarks with human annotations, according to results published by the researchers.
AI model outputs first speech audio in 390 ms on NVIDIA GB10
A single model takes text, images and speech as inputs and uses a reference voice to synthesise speech.
Compressed translation models take up to 5.3 times as long
The study abstract reported lower memory use and changes of about one point or less in most aggregate translation scores.AI illustrationGoogle Gemini automatically uses available connected apps
Google’s help page does not say whether Gemini includes delivery fees when comparing prices.
OpenAI releases a recorded demo of the Codex Security Plugin
The recording follows the workflow from getting started with the plugin to reviewing the results shown on screen.CaDO automates answer repair in causal reasoning datasets
The researchers turned plain-language questions into queries they could verify and compared how often each method changed answers that were already correct.
Wrtn outlines how creating play could become a job in AI era
Wrtn argued that the leisure industry would become more important if working hours fell.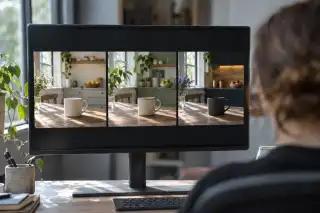
Simplex AI releases code for its on-device Linger AI agent
Adopting Linger depends on which tasks it can handle offline and whether the licence permits the intended use of the code.AI illustrationSTAGE identifies causal links across disaster posts
Researchers reported that training STAGE on links between posts improved its performance more on wildfire posts than on Hurricane Harvey posts.
KIWI-EP cuts the time vLLM takes to generate an output token
KIWI-EP changes how tokens are sent to expert models and how the results are collected.AI illustrationJoint model detects more errors in first-person video
In the researchers’ evaluation, a model that jointly predicted which step was attempted, when it happened and how it went scored higher at detecting errors than a model that handled those tasks separately.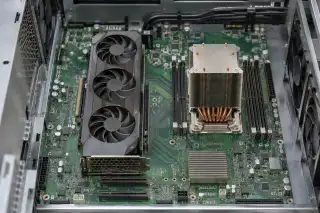
Models vary in reading context in English and Mandarin tests
Researchers reported that language models were more likely than human participants to take remarks literally in dialogue questions.
JAPANNEXT launches its JN-X6K2 6K monitor for media creators
The published specifications give the matte panel’s resolution and refresh rate, while colour coverage varies by gamut.AI illustrationTech outages disrupt email, banking and air travel
The outages affected email, banking and air travel in different ways, and Tech Xplore did not identify which, if any, involved AI.
ElevenLabs adds video ad editing and dubbing to Ads Engine
Advertisers can change an existing ad’s opening or soundtrack, or dub it into another language, without a reshoot.AI illustrationElevenLabs unveils speech recognition models for two uses
ElevenLabs tested how well Scribe v3 distinguished speakers in recordings, while Scribe v3 Live detects when someone has finished speaking.AI illustrationSingle-pass model gets 46.0% on medical multiple-choice test
The researchers kept the language model fixed and trained only the part that compares questions with answer options.
Study tests language model weight repair without retraining
A fixed projection matched live selection closely on Pythia, while both procedures used the same family of operations in a separate test with a compound fault.
NeuroFusion’s Cerefin ranks first overall on ForecastBench
Scores for economic and financial time series and for prediction-market questions carry equal weight in the overall ranking.
Arithmetic circuits go into model weights without retraining
A paper compared writing arithmetic rules directly into model weights with fine-tuning on examples.
ElevenLabs and OpenAI take different paths to cloning voices
DEV Community compared how ElevenLabs and OpenAI clone voices, how much users can adjust them, how quickly they generate speech and what they charge.Higgsfield publishes AI video ad guide for restaurant owners
The guide advises restaurants to start with photos of their own dishes and cut shots that change the ingredients, portion size or plating.IDWorld identifies people by body features without rendering
The model identifies people by predicting how their features would look in the same outfit, from a fixed angle or as a silhouette.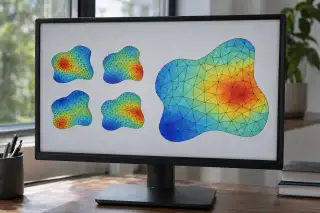
Longer histories improve forecasts of customer behaviour
The paper reported that extending the observation window improved forecast scores by more than the differences observed between sequence model families.
ReLay cuts model call costs in analogue circuit layout tasks
The researchers recovered code from existing circuit layouts and added recurring design procedures to a library of shared functions.
Image caching lowers word accuracy in Z-Image generation
The researchers reported that GuideCache restored how closely images followed prompts by recalculating only the parts with the largest predicted errors.
Reusing FAct improves image classification accuracy in tests
FAct ranked first in 11 of 16 test settings when training settings were tuned separately for each activation function.
TuringPAI-Drive generates in-vehicle driving paths at 12 Hz
The paper said TuringPAI-Drive ran in the vehicle on a single NVIDIA Orin-X chip.AI illustrationNew rule cuts false safety approvals in gallbladder surgery
The new rule cut false approvals in videos where experts disagreed, but also approved fewer videos on time when they met the safety standard.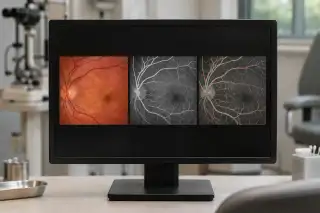
Structured records flag the same missing results as answers
The author drew no conclusion about the effect of adding a record after the evaluator fell short of a pre-set human validation standard on the key category.
ElevenAgents charges $0.16 a minute for calls over the limit
ElevenLabs applies a separate per-minute rate to calls above the simultaneous call limit and explains how queues and phone lines affect capacity.AI illustrationAI video costs include footage dropped from the finished cut
A generation fee covers one attempt, while the cost per second of the final cut also includes what was spent on unused footage.
Qwen3-VL 32B varies simulated gaze with a basic prompt alone
Researchers reported that asking the model to describe where a user would look before simulating gaze made the results sensitive to changes in profile traits unrelated to gaze.
TETHER maps long documents from their tables of contents
TETHER matches text blocks to table of contents entries to find where chapters and sections begin and end, without additional training.
Databricks opens public beta of Genie ZeroOps pipeline agent
The AI agent investigates logs when it detects a pipeline failure and tests proposed fixes in an isolated environment.
TRAC speeds up diffusion translation by adapting text length
In the researchers’ tests, TRAC reduced model calls and lowered the macro-average COMET translation quality score by 0.02 points.
AI bug reproduction is linked to more valid software reports
Researchers found that bug reports were more likely to be valid when AI helped reproduce or diagnose the error.
RoCoKV speeds up reasoning in a test against a full KV cache
Researchers designed RoCoKV to vary how much it compresses the KV cache according to the model’s confidence during inference.AI illustrationEx-Anthropic researcher criticises AI work by big businesses
Jacob Coxon, who accused Anthropic of putting lives at risk when he left, questioned in an AFP interview who should develop powerful AI.Databricks outlines 4 AI agent designs for regulated sectors
The designs set an agent’s authority according to whether fixed rules can determine the outcome or a person needs to make the decision.A logo changes AI responses to visible and infrared images
Researchers measured how often the same target response ranked first for both visible-light and infrared images.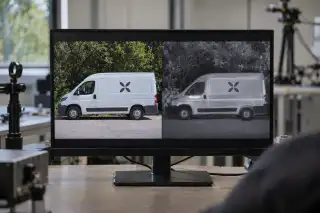
Gwangju roundtable weighs support for Korean NPU chip trials
Server and edge chip makers discussed performance testing and ways to work with global companies on certification and market access.
AMD brings AI agent inference to neural chips built into PCs
Unsloth Desktop lets AI models run inference on a neural processing unit built into a PC.
AI reads mammograms better by comparing images of both sides
The public abstract does not say how much diagnostic performance improved.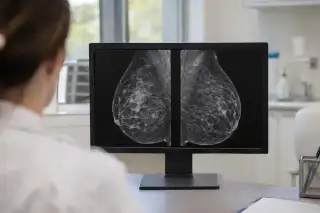
AI agents build retrieval-augmented generation from scratch
The combination that led the benchmark without starter code also improved human-designed systems in a separate experiment.
AI calorie estimates fail to scale with stated food weights
Multiplying each model’s calorie estimate per unit of weight by the stated food weight reduced errors for small and large portions.
Review urges reasoning audits for medical AI certification
The authors said tests focused on correct answers can miss faulty causal reasoning.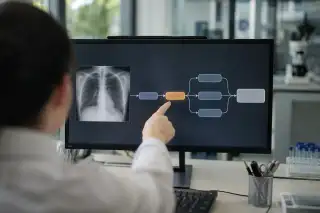
Anthropic sets Class A IPO share price at $83.00 per share
The offering totalled 1,127,000,000 shares after the underwriters exercised their option to buy additional shares in full.Video token selection ranks high without using the questions
Researchers reported that splitting questions into meaningful cues helped find specific evidence when few video tokens could be kept.
Anthropic closes initial public offering at $83.00 per share
Anthropic received about $91.6 billion from the IPO before offering expenses and closed a separate private placement at the same price per share.AI sales automation faces reliability challenges after demos
From company research to preparing follow-up actions, making a workflow run reliably in day-to-day sales is a separate engineering challenge from getting it to work in a demo.
Ideogram publishes API pricing for 4.6 image editing model
Editing fees vary by resolution, and Ideogram 4.6 ranked first in a multi-step editing benchmark that used different settings for its predecessor.
4-bit method cuts reasoning costs in a vision-language model
The researchers designed QL-VLM to preserve how a model retrieves information from images and text and to keep its reasoning aligned with the full-precision model.
Moonshot AI fixes Kimi Code CLI web input bug
The update also fixes a bug that reset the selected reasoning effort to the model default after a prompt was sent.AI illustrationGoogle’s Genie 4 lets users edit worlds as they explore them
Google said users can change the weather as they explore, while Genie 4 generates ambient sound and character dialogue that adapt to the scene.Lunit adds breast imaging AI at Korean university hospital
Lunit announced a breast imaging AI deployment, while the supplied DHP excerpt did not substantiate the overseas revenue shares cited in the Korean article.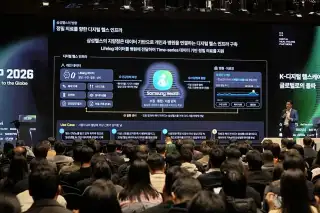
Google showcases five Gemini 4 Carbon projects
Google highlighted real-time particle simulations and public-data tools, alongside paid developer access.
Databricks opens new US government cloud environment in beta
The beta is for non-production workloads, with AI features and government security authorisations planned for later.Algorithm lifts program accuracy by up to 22 points
An algorithm that selects input-output examples improved program induction accuracy over an agent using only a language model.
Cohesity expands beyond backup into security and AI
Cohesity’s overall customer base in Korea and adoption of its AI analytics products need to be read separately.
Instagram unveils tools targeting reposts and AI edits
The announced tools target unauthorised reposts and AI-modified videos, but TechCrunch's explanation of the announcement's timing remains an interpretation.
Darwin claims lowest forecast error across 28 categories
Darwin’s performance claim rests on company-published figures comparing its AI weather engine with established forecast models.
AG-JEPA improves early cognitive impairment classification
Researchers reported that learning features of specific brain regions improved diagnosis and disease progression prediction.
Study compares voice AI for Spanish freight negotiations
The study compared errors in recognising spoken amounts and response delays measured from the listener's side.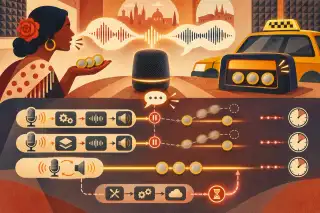
SK Innovation selects three AI startups for funding
A startup helping special education teachers with administrative work won the top prize after technical validation and mentoring.
KMS Lab wins POSCO portal replacement project
The company-wide portal project uses KMS Lab’s own platform, but winning the contract and proving model performance are separate matters.
Flexible display serves both people and robots
People read visible colours while robots use cameras to read near-infrared patterns on the same screen, according to AI Times.
Galaxy and Star Plus Legend plan companion robots
The agreement adds companion robot development, robot parks and robot tours to the companies’ existing entertainment partnership.
WebArena-Pro evaluates audio and video web agents
Codex and Claude Code share the highest reported score, each paired with a different model.
Apple TV app plans a video podcasts section
The plan to bring video podcasts to more screens is distinct from the reported prospect of developer testing.
SuperDial revamps voice AI to cut time on AI-to-AI calls
The change to healthcare voice automation needs to be assessed separately from any resulting reduction in computing work.
CTF-Dojo offers 658 tasks for language model training
CTF-Dojo provides verifiable execution results for agent training, while its published performance comparisons concern CTF security challenges.
Gemini rolls out free booking and shopping tasks
Korea is included in the free rollout, while advanced features and task requests by text and email start in the US.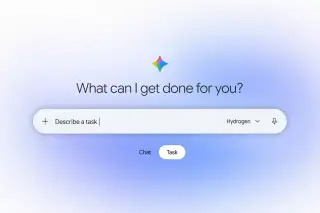
Google finds AI hacking tool on an attacker's server
The reported discovery puts a design linking public security patches to attack code in an attacker's toolkit, beyond research demonstrations.FlashREINFORCE trains agents with one run per input
FlashREINFORCE researchers said their method reduced repeated runs per input while maintaining training stability.
ElevenLabs plans Kotoba acquisition for Japanese voice AI
The acquisition targets Japanese enterprise conversations, but ElevenLabs has not disclosed a product integration timetable.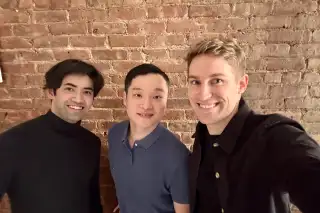
Translation compression quality depends on the metric
A translation model compression study found disagreement between automatic metrics and used candidate reranking to improve both compressed systems.
Apple adds disk access controls for Mac AI agents
Disk access permissions are the starting point for deciding which development tasks to assign to an AI agent.Korea AI strategy panel discusses research and factory plans
The discussions linked AI use across research and development with overseas expansion strategies for unmanned factories.
CoT2Graph improves prediction of correct AI answers
Researchers linked correct reasoning to early planning and failed reasoning to overloaded synthesis steps and broken dependencies.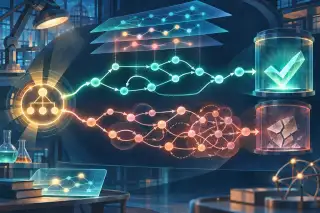
Naver tests creator recommendations atop its home feed
The beta test selects professional creators’ content based on users’ age groups and daily routines.
Phone prescription reader reports 67% medication recall
A study using the same prescription photographs reported fewer missed medications but longer processing times.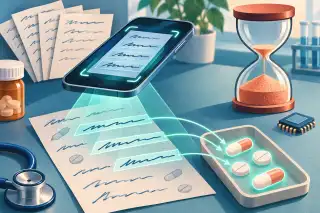
CECAR speeds on-device inference through expert selection
CECAR adds predictions of expert reuse to cache-aware routing for on-device inference.
Google reports AI attacks that analyse and exploit patches
The significance of reported automation from patch analysis to attack execution lies in how much work proceeds without human intervention.Dunamu papers gain main conference and workshop acceptance
The acceptance routes identify where the research will be presented; assessing performance requires each paper's experimental conditions.
Spatial reasoning gains show limited generalisation
Researchers reported gains from spatial training questions alongside limits that varied by model.
Language model edits depend on evaluation conditions
Papers on refusal removal and vocabulary trimming assessed model behaviour after edits alongside the conditions used to evaluate it.
Korea plans entrepreneurship events on failure and AI
Planned events across Korea, online and in person, aim to share lessons from failure and strengthen problem-solving skills using AI.
CivilBench exposes limits in AI numerical reasoning
The researchers said numerical priors and external knowledge helped only to the extent that models could interpret and use the evidence.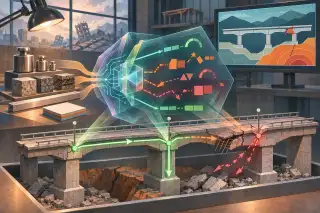
EEGProbe finds an alignment bottleneck in vision models
EEGProbe tests whether vision-language models need brain signals to answer questions and can connect those signals with other forms of information.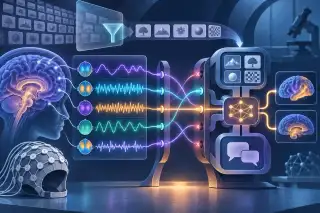
Cohere adds video search to Compass
Cohere introduced a feature to search videos alongside documents and began recruiting design partners.
AI time savings outpace gains in work completed
Average time savings increased for workers using generative AI in Korea, but the amount of work completed did not rise proportionately.
ETRI reshapes six research roles around national missions
The proposed changes link ETRI’s responsibilities to how it carries out research, supporting results from its strategic research programmes.
KOCCA showcases 64 AI projects from creator training
Films, animation and virtual reality content showed how creator training combined professional expertise with AI technology.
Cohesity links attack prevention with data recovery
Cohesity's reported cyber resilience strategy brings attack prevention and data recovery into the same security framework.LVMH media division partners with OpenAI on ChatGPT access
The partnership links support for journalism with wider reader access, highlighting AI's roles in content production and distribution.Gemini adds 66 regional voices, including Korean
Google said users’ chosen voices apply across the Gemini app, from live conversations to chat responses read aloud.BLiMP-RO links training data to Romanian grammar scores
BabyBabelLM generally outperforms video captions at matched training sizes in the reported tests; the abstract reports no independent replication.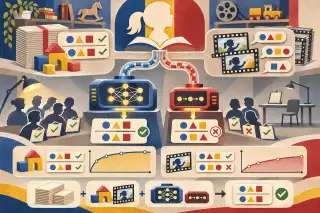
Databricks launches index comparing AI coding costs
Databricks reported different costs per task for models with equal success rates in its own coding evaluation.HyperAccel plans eight-LPU inference server debut at SC26
Company-published tests comparing throughput per watt and per dollar accompany plans for a live demonstration linked to servers operating in Korea.
SceneAgent separates scene-building knowledge from engines
SceneAgent separates reusable scene-building guidance from engine integration, making execution cost part of the case for reuse.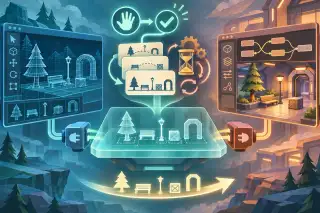
AI-written code improves unsolved scheduling benchmark
AI-written code achieved a smaller gap to the theoretical lower bound than commercial tools in a comparison using the same hardware and execution budget.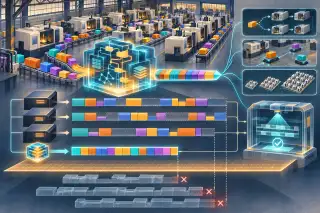
Forecast benchmark tests text that conflicts with trends
The study examined when text that contradicted historical trends increased forecast errors and how limiting forecast adjustments helped.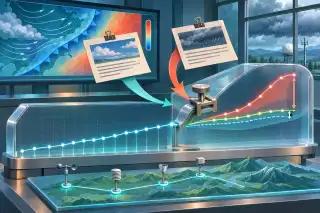
OpenAI introduces computer-use agents for healthcare
The announcement pairs improved clinical answers with tools for carrying out tasks across healthcare software.Google Maps adds trip planning and appointment search
Trip itineraries and saved-list search cover all Ask Maps markets, while appointment search launches first in the US.
ACE-CaP-0 reuses AI-written robot control code
ACE-CaP-0 freezes AI-written code for reuse, while its reported success rate comes from the authors’ own real-robot tests.
Fewer bird-deterrent responses leave crop protection unclear
A reported fall in device responses is a separate claim from a reduction in crop damage.
sra-riskgate totals wallet spending across chains
sra-riskgate aggregates spending by sender wallet but does not guarantee that simultaneous checks cannot both pass before spending is recorded.
Lens tests satellite search without target-specific training
Lens searches image features with reduced positional bias and reports performance at the best threshold for each land-cover class.AI illustrationSemes includes AI applications in engineering challenge
AI applications feature among practical proposal areas in a competition intended to identify talent and promote technical exchange between industry and academia.
FEND aims to identify who answers voice AI calls
The proposed framework distinguishes people, voicemail, automated phone menus and AI to help voice agents choose how to respond.
Tencent launches Hy4 flash with low-cost API pricing
Vercel announced Hy4 Flash availability through AI Gateway with discounted token rates through 29 Nov 2026.
STaG adapts person search without new human descriptions
The proposed method uses descriptions from an existing environment and images from a new one to address text alignment and visual differences.AI illustrationPERFARENA evaluates the cost of running AI-generated code
The open-source tool assesses code correctness alongside runtime, memory use and energy consumption.AI illustrationAI recommendations yield 209 new unregistered package names
The registry checks distinguished package names first observed that week from names registered after an AI recommendation.
Runway releases robot-control model weights
Usage rights and links to video production are the criteria creators need to assess the model release.
Manual research extends beyond search to source judgement
A post introducing NoteGPT described source assessment and the extraction of key points as part of the research workload after search.AI illustrationRAWATTA processes 200 images without additional training
The method uses 8-bit precision for attention calculations and retains 16-bit precision only in layers that require it after a calibration check.AI illustrationQualcomm showcases agentic AI at Korean technology event
TechM reported that Qualcomm presented AI that goes beyond answering questions to understanding context and proposing and carrying out tasks.
Korea Midland Power robot challenge draws 16 finalist teams
The competition separates idea planning from product development and use to identify robot technologies for power plants.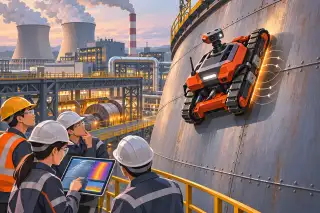
Panasonic expands physical AI work with about 250 staff
Panasonic made spatial recognition and precise robot control its development priorities, with business results in manufacturing and logistics as its goal.
Fortinet appoints former Dataiku executive as Korea head
The new country head’s experience in data and cloud computing should be read separately from Fortinet’s future business direction.
Unfinished medical AI reasoning yields existing diagnoses
Researchers separated diagnoses already present in reasoning from answer completion and diagnostic correctness.AI illustrationAI proposes excess experiments in mineral exploration test
Researchers reported high recall but low precision when AI selected experiments to test geological hypotheses.
LLM evaluation framework looks beyond task scores
Researchers proposed a framework to assess how language models process knowledge recall and reasoning tasks.
AI-Voyager aims to help citizens revise AI rules
The proposed system links answers to government documents, but study participants rarely followed citations to check the source.AI illustrationSmall model decisions remain sensitive to who takes part
Pooling evaluations left participant effects intact, prompting researchers to recommend candidate sets and margins over forced rankings.
Google DeepMind benchmark tests professional AI tasks
The assessment covers complex visual analysis and the completion of professional work, including reports and spreadsheets.Bandicam adds motion transfer to swap video subjects
The company outlined uses for character content and product adverts that retain the original video's movement.
Qwen4-Max launches with preview access terms unresolved
Qwen4-Max's launch notice lists tool support separately from the preview's Token Plan access restriction.
Naver cuts SNOW image AI resources through GPU sharing
Naver reported savings from switching to LitServe and sharing GPUs but did not publish before-and-after response times or throughput.
Dropshot AI reports tenfold growth in content generation
Dropshot AI combines image and video models in a Korean-language web service, with 510,000 cumulative registrations reported separately from its content total.Seoul National University AI cuts remote calls by 43.3%
The reported approach combines sensor control with AI inference to reduce calls to remote models.
Metal Sandbox raises Mac command throughput in tests
Metal Sandbox’s command throughput tests and session-based estimates used different conditions.
Content marketing automation starts with drafting
A proposal to change repetitive drafting before adding another scheduling app puts time for client work at the centre of content marketing automation.
Beyerdynamic unveils four black-edition studio headphones
The four-model range shares an all-black finish that the report links to a restrained professional audio aesthetic.
Claude helps Jeep owner pass emissions test
The reported parts cost and the owner's wiring skills both matter when assessing how Claude helped.
ElevenLabs preference rests on developers’ needs
A comparison favouring natural speech and easy integration makes development goals central to the choice of voice service.
Siseon AI gains approval for three M.AX alliance divisions
The announcement covers participation in a manufacturing AI alliance spanning industrial complexes, defence and factories.
Seedance 2.5 clip prices vary by purchase route
A comparison of list prices for matching video outputs showed why credit amounts need to be read against the cost of buying a clip.
Suspected vivo X500s gets Dimensity 9-series chip claim
A tipster identified the chip family, while the phone’s name and position in vivo’s range remain assumptions.
Satellite image vectors predict event completion dates
Researchers report using differences between satellite image vectors to collect event data without manual labelling and train a prediction model.
An index maps outfit and pose combinations in ComfyUI
A DEV post focused on finding a desired outfit and pose combination rather than improving generation quality.
CineMME reveals gaps in linking dialogue to speakers
Researchers found that visual information helped some video questions but could hinder dialogue-based reasoning.
Icerti targets Singapore with AI video security
A safety and security programme gave Icerti a venue to present its technology as it pursued entry into Southeast Asia.
An XDA writer puts local AI in control of a Windows PC
The account turns on a distinction between the writer's convenience and evidence of the AI's performance.
AI-favoured words rise 29% on least-edited sites
A study linked vocabulary growth to how often answers were edited, but did not observe actual model use.TFC-MMFD posts 99.40% accuracy in bearing fault diagnosis
The researchers evaluated the model on public datasets covering varied operating conditions, but the abstract disclosed no validation results from industrial equipment.
ThermalSplat rebuilds 3D scenes without camera positions
The method reconstructs new scenes from thermal images without colour guidance or additional training for each scene, according to the paper.Evaluation methods reverse image AI model rankings
Similar overall scores masked disagreement over individual images, while automated model rankings differed from human assessments.ChJGBench tests AI generation of Chinese court judgments
Researchers reported that legal models' strengths over general-purpose models varied by evaluation category.MITRA-Swarm lifts Sanskrit translation score by 0.63 points
The researchers reported roughly nine times the inference cost per verse compared with a single model.Bland unveils Tofu-1 to listen while speaking on calls
A DEV.to report described simultaneous listening and speaking on calls and Bland's plans for a family of speech-to-speech models.
Doosan Enerbility shares AI power plant maintenance tools
Predictive diagnostics and remote monitoring put power plant operating data at the centre of a technical exchange on maintenance.
ElevenLabs adds creative staff for enterprise ad production
Creative specialists help build production workflows or deliver finished ads, while client teams retain final approval.
Yahoo Scout to pay publishers for content in AI answers
A publisher-led nonprofit links content use in AI answers to payments to publishers.
Google Flow adds tools to rework phone footage
Google introduced a tool that generates multiple camera angles from one take of phone footage while preserving the actor’s original performance.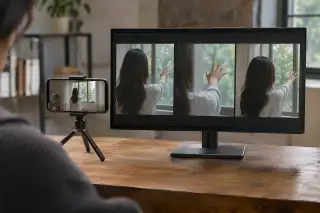
GPU-CPU method improves optimisation scores by up to 4.9%
The method passes GPU-calculated variable values to CPU solvers without training data or a pretrained model.Produce robot trial targets 24-hour unmanned operation
The trial centres on handling multiple crops in one facility and processing peak harvest volumes around the clock.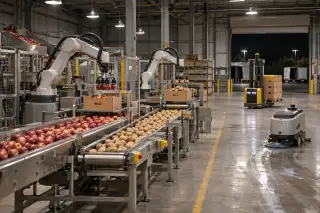
IceNest cuts Arctic passage timing error in simulations
The reported reduction in passage start-date error comes from simulated voyages and needs to be distinguished from accuracy in forecasting ice distribution.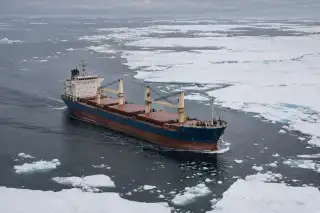
Per-page AI crawler fees would keep sites free for people
A DEV.to post proposes sharing the cost of delivering public content with the AI crawlers that collect it.
YouTube AI dubbing puts revenue beyond viewing gains
A DEV Community post identified viewer location, advertising demand and dubbing costs as factors in whether wider viewing translates into revenue.
TikTok trend video comparison puts minimum packs at $6.99
The comparison prices the smallest purchase pack needed to make a video, rather than an individually sold clip.Higgsfield leads Ramp's image and video AI adoption rankings
The ranking counts businesses paying through Ramp, excluding individual creators and companies using other payment methods.Agentforce Coworker reaches 100,000 users in first 35 days
Salesforce’s early user count measures adoption of Agentforce Coworker, while workplace agents need to be assessed on task results.
Gemini features in a Black Friday deal-tracking case
Android Police’s assessment that the approach worked should be read within the scope of the individual use case.
1 week agoNov 15
Anthropic proposes safety tests for whole conversations
Anthropic argues that AI safety evaluations should assess both compliance with harmful requests and excessive refusal of harmless ones.
Sophon tuning improves spatial reasoning in open models
Researchers traced spatial reasoning failures to a bottleneck in how models route information into answers.
Genie answers in Slack using the asker's permissions
Answers generated with the asker's permissions are visible to the channel by default, while document changes require user approval.
MIGRO retains 99.9% of rebuilding quality after model switch
Researchers designed MIGRO to separate memory from individual language models so successive models can read and extend existing records.MemCrafter refines AI video prompts to aid memorability
Researchers proposed a method that repeatedly revises video generation prompts using estimated neural responses to predict memorability.
L’Oréal joins China import expo with three Korean startups
The programme targets commercialisation, but exhibiting technology and securing business results are separate outcomes.
Honor sets Magic9 Pro Max Malaysia launch for 24 Nov
The Malaysian unveiling follows the phone's debut in China, while buyers still need local pricing and a sales start date to plan a purchase.
Ablearn webinar addresses organisational readiness for AI
Plans to adopt physical AI do not establish that employees are ready to work alongside it.
MOSS-Live trails GPT-Live-1 on multi-turn tasks
MOSS-Live's background-speech error rate and multi-turn results called for separate readings of what each assessment measured.
Luma links video and sound generation with targeted editing
Luma described a workflow that combines sound and video generation with edits that preserve approved compositions.
DEV post outlines summarisation training for 135M model
The training methods named in the title and evidence of summarisation performance need to be assessed separately.
462 in totalWritten by Gyeol HanRSS feed