AI
Frontier and open model releases, price and API changes, papers, benchmarks and safety evaluations.
Weight deletion delivers gains on par with full fine-tuning
Researchers reported lower storage needs for training results alongside preserved existing abilities.
1 week agoNov 10 – Nov 15
Image segmentation method finds look-alikes without training
The method finds candidate objects, compares them with a reference image and outlines the matching object.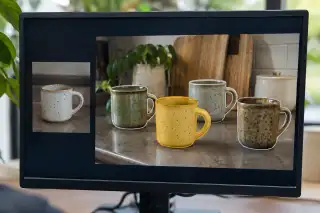
AFTER-WM adapts robot predictions without changing models
Researchers proposed combining short-lived and lasting corrections to adapt robot motion predictions while keeping pre-trained models unchanged.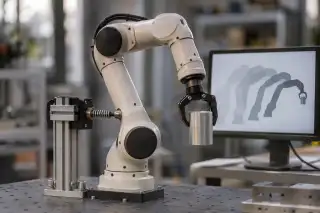
Distinkt launches AI-assisted talent management agency
Distinkt combines professional agents with AI workflows under a non-exclusive representation model, according to ZDNet Korea.
FreeDeshadow targets shadows cast by selected objects
The framework lets users select an object with a dot, line, mask or text to remove only the shadow it casts.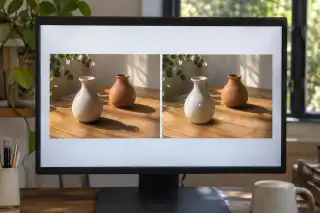
Kakao Ventures partners with Higgsfield to support startups
Kakao Ventures will support platform adoption by its portfolio companies, while Higgsfield will provide training and technical support, according to AI Times.
WHOOP rolls out Humans social features for members
Members choose which health records to share and who can see them, with an option to hide information temporarily while keeping existing settings.
PhysICL predicts physical fields without retraining
PhysICL uses simulation examples to predict physical quantities across a new mesh while keeping its model weights fixed.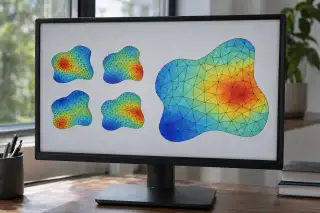
Apple Watch Ultra 3 discounts start at $549.00
The starting price applies to eligible models, and the report’s retailer affiliate disclosure belongs alongside its price comparison.
Pakistan port AI design sets ownership and data boundaries
The proposal links operator ownership with domestic model execution and excludes sending customers’ cargo information abroad or to foreign model services.
AI video orders hinge on each team member’s available hours
Higgsfield’s guide makes editor workload and time spent waiting for client approval central to decisions on taking new orders.
Luma sets out editing workflow for consistent AI characters
Luma AI's guide centres on carrying approved characters into later scenes, but provides no comparison of tool performance under the same conditions.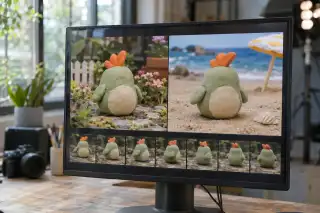
Luma Labs outlines editing tools for approved B-roll
The guide covers workflows from generating new footage to revising parts of approved shots.
Keeping a pilot AI model raises ticket-routing cost concerns
A DEV post questioned whether a model chosen to prove a support bot works remains justified for routine ticket classification.
PREWARN separates failure detection from early warning
Researchers said detectors with similar response classification scores differed in their ability to warn before a language model failure began.
Classifier outperforms model at detecting perturbations
Researchers cautioned that identifying a perturbation's location does not imply broad access to a model's internal computation.
Decider weight release carries repository access conditions
Decider weights are reportedly offered under an Apache licence, while instructions for using the full model include authentication for a private repository.
OpenAI unveils ChatGPT Wallet for agent purchases
ChatGPT Wallet lets agents complete purchases with user approval and existing card protections, OpenAI said.
AI copilot lets engineers steer structural design
The reported approach moves engineers' input into the design process, instead of leaving revisions until after an algorithm finishes.
Google expands AI agent monitoring and cost controls
Optional conversation logs go into customer-owned tables, while daily token quotas are available in preview.
TKNP raises long-context AI throughput by up to 1.7 times
Splitting a model across servers while keeping each request's attention on its assigned server is central to TKNP's throughput comparison.
AVCC adds human benchmark for next-speaker prediction
The benchmark compares human and model predictions on the same conversation samples recorded with a single camera and microphone.
Alania-2 lowers word error rate in Turkish speech synthesis
The paper also reported results from a text normaliser that spells out numbers and names as Turkish speakers would pronounce them.
ElevenLabs raises Dutch identity-check accuracy to 90%
ElevenLabs fine-tuned the model with KPN using Dutch-language data but did not disclose the evaluation sample or scoring criteria.
B3 speeds up self-editing diffusion language models
The method needs no additional training or parameter tuning, and researchers reported generation quality on par with the base model.
Emotional headlines raise AI severity ratings
Providing the article body reduced the effect of headline wording on AI severity ratings, the paper reported.
Amazon targets workforce change with job training investment
The education programme combines skills development for changing work with preparation for new occupations.
Family Link cannot guarantee Gemini homework safeguards
Parental settings that make homework outsourcing harder should be distinguished from a guarantee that they prevent it.
AI video detectors miss most fakes after reposting
Researchers identified changes in generators and content, alongside repost compression, as separate causes of weaker detection.
Luma puts approved footage at the centre of AI revisions
Luma outlined a workflow that preserves performance and timing while connecting still-image editing to later revisions.
MiniMax unveils model for direct high-resolution images
DigitalToday reported that MiniMax's image model supports generation without separate upscaling, editing and distributed weights for developers to run it themselves.
Drone disaster model uses 0.1 MB of storage
The picoEmergencyNet researchers presented a design tailored to disaster classification instead of increasing model size.
KT wins Prime Minister’s Award for telecoms facility safety
ZDNet Korea reported that KT used real-time data to identify warning signs and extended its facility management model to public and private sites.
Pickle halts KakaoTalk integration after one day
Choosing tasks to delegate to AI also means checking what the connected service permits.
AI benchmark tests nonverbal reasoning in early childhood
Researchers reported that vision-language models recognised context well but struggled to interpret specific behavioural and interpersonal cues.
TTSFree.in API offers speech synthesis in 23 languages
A developer guide starts with Hindi speech generation and covers translation and speech recognition.
Holiday Extras uses Codex to build on customer expertise
OpenAI presented app improvements, higher booking conversion and new growth possibilities as benefits of Holiday Extras' use of Codex.
QNAP expands into data recovery and private AI for 2027
The strategy responds to business storage decisions that now encompass continuity, security and AI use.
Samsung SDS is preferred bidder for KNOC AI project
The project combines retrieval-augmented generation using internal data with multiple AI agents for workplace tasks.
Seedance 2.5 Flash costs $0.152 per second at 720p
Speed and output-quality comparisons are BytePlus claims, while ModelArk API access remains scheduled for 15 Nov.
Maum AI joins defence AI consortium
The reported military, industry and academic partnership lists on-device AI and autonomous robots as areas for defence cooperation.
Buzz lets Block staff choose models for each coding agent
Buzz brings colleagues’ code review and model selection for individual agents into one workspace, but Databricks disclosed no cost figures for different combinations.
Synthetic emissions scenarios cut climate AI training runs
Training on extreme emissions changes could reduce simulation runs, but that claim needs to be assessed separately from prediction quality.
LIS claims safety alignment gains with a smaller dataset
The researchers address safety and unnecessary refusals together, but the abstract omits evaluation model names and benchmark-specific scores.
Google previews two AI text functions for AlloyDB
Google puts classification and extraction into SQL, while processing still includes sending inputs to models.
Luma puts follow-up editing at the centre of poster tools
Luma used editing after generation as a comparison criterion and placed its own features at the front of its guide.
Luma puts consistency first in video-to-anime conversion
Luma sets out a production workflow that preserves approved motion and connects conversion with further editing.
Luma puts revisions at centre of mobile AI video choices
Luma framed revisions and final delivery as criteria for choosing mobile AI video tools, linking those priorities to its own services.
Higgsfield guide leaves final checks to AI video creators
Higgsfield’s guide leaves fact-checking and editing with creators while separating AI disclosure from YouTube monetisation eligibility.
Google launches API to score predefined choices
Shared input is billed once per request, while Google's latency figures apply to specified input lengths and question counts.
Chariot launches speech model for 11 Indian languages
The reported features extend beyond multilingual support to code-mixing, instant voice cloning and contextual speech generation.
Seagate unveils FireCuda Forge with SSD responsiveness
DigitalToday reported Seagate's claim that FireCuda Forge combines SSD responsiveness and HDD storage capacity in one drive.
Multi-word training cuts English tokens; model tests remain
Researchers reported compression gains but did not evaluate models trained with the new tokenizers.
Legal AI training method balances reasoning and answers
The method balances learning from reasoning and final answers, then adjusts auxiliary rewards according to their effect on the final evaluation.
Language gaps persist in document understanding benchmark
Researchers reported that larger models did not narrow performance gaps between languages in the MDU benchmark.
ElevenLabs opens marketplace for industry voice AI apps
Businesses can find industry-specific apps and discuss deployment with partners, while purchases through existing ElevenLabs commitments remain a future plan.
AI research forecasts broaden beyond company insiders
External researchers joined company insiders in forecasting rapid AI progress, but the forecasts concern when research capabilities might emerge.
Intel sets out PC strategy for AI agents
Intel outlined a strategy linking AI agents that carry out PC tasks with wider AI use in healthcare, manufacturing and robotics, according to AI Times.
Seoul forum examines AI research and global cooperation
Korean research institutions and a science federation jointly hosted discussions on AI research strategies involving experts from the US, Europe and Korea.
CaseScope finds instability in AI pathology diagnoses
Open models were more affected by specimen-site information than by additional images on teaching cases, the researchers reported.
Place search accuracy falls when source views change
AcrossPlace researchers report lower place-search accuracy when retrieval images differ from those used to generate descriptions.
Naver Mate support raises AI contribution reward debate
The structure of creator support and its interpretation as payment for AI contributions require separate readings.
Adobe brings music generation to the video timeline
Adobe offers free music generation in Firefly and brings music and sound effects into the Premiere editing workflow.
ElevenLabs extends free voice restoration to singing
Songwriters of North America checks eligibility for free music access, while hospital patients receive voice restoration support through rehabilitation teams.
MICRO benchmark pairs retinal images across surgery phases
Researchers proposed a one-step learning method that aligns retinal images using similarities in their blood vessel structures.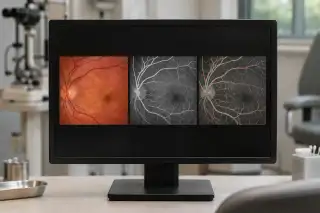
PolyRoute sets benchmark for routing queries in 12 languages
All test messages and answers are AI-generated, while a statistical classifier scores 91.9% in the researchers’ published results.
FERN improves table retrieval without generative AI
FERN reported gains from reranking on Spider, but its Fiben comparison used different question sets.
ElevenLabs opens free early access to ElevenAI meeting app
The enterprise app takes meeting notes with every attendee's consent and delivers individual summaries and follow-up tasks.
ElevenLabs expands enterprise AI partner programme
The company expanded technical certification and joint sales support and pledged not to compete with partners for implementation services.
ElevenLabs partners with McKinsey on enterprise AI agents
The alliance pairs voice technology with enterprise systems integration to handle customer requests, with insurance among its target uses.
Breggz launches Zohn 2 with IMAX Enhanced certification
The Zohn 2 combines sound tuning with a five-driver design aimed at music and film listening.
Seagate introduces FireCuda Forge with Alkemi platform
Seagate describes FireCuda Forge as a single drive combining SSD responsiveness with HDD capacity.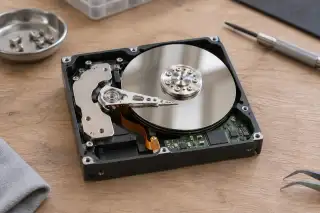
Gemini and Claude define the scope of phone tasks
Task support depends on apps and connected features, while Gemini screen automation in South Korea also depends on device eligibility.
Databricks adds Power BI metric publishing
Teams can request preview access through their account teams and automate publishing to keep metric changes in sync.
LiteLLM Rust claims depend on benchmark conditions
Processing overhead, memory use and requests per dollar need separate scrutiny before they support an overall performance judgement.
Australia’s AI safety mandate raises a question of focus
Making AI safeguards mandatory and choosing the right risks to regulate are separate policy judgements.
Safety score calibration cuts harmful responses in VLM test
Researchers report fewer harmful responses after training a vision-language model with calibrated scores and limits on harmful assistance and unnecessary refusals.
HintErase targets subtitle removal despite detection errors
The model uses the original video and region hints to remove missed subtitles while preserving wrongly marked background.
Google Search adds Gemini 4 Hydrogen for complex queries
Google outlined changes to how Search splits questions and presents results, but published no comparative figures for its wider website coverage.
AI video ad review framework gives humans the final say
Reviewers accept or reject model findings and send confirmed problems to matching editing tools.
OpenAI commits $2 million to child AI safety research
The funding supports research on shared tools to measure AI's risks and opportunities for young people.
SolidWorks CEO sets out requirements for industrial AI
AI for manufacturing must model deformation and fluid flow as well as product geometry.
Cisco sets conditions for integrating Korean AI models
Product competitiveness and customer demand govern model integration, while support for Chinese models remains separate from competition in infrastructure.
FoleyForge proposes sound editing that preserves identity
The design combines a training pipeline that creates editing examples with controls for loudness and edit strength.
Databricks unveils Genie for autonomous enterprise work
Genie connects business context with search while administrators control tool access, approval requirements and spending limits.
Google prices Gemini 4 Hydrogen API input at $1.50
Google applies flat pricing across the full input context and positions Hydrogen for coding and work involving multiple models.
IBM and Microsoft unveil enterprise AI agent platform
The reported scale includes agents and related technology assets, while the platform centres on connecting them to enterprise workflows.
GS Shop reports up to 3.9 times the AI search exposure
The reported gain concerns search exposure, measured after GS Shop revised its product information for generative AI search.
E2VID yields 40 person detections in reconstruction test
Researchers reported a detection gap between reconstructed images and direct representations even in a retrospective comparison that capped background false positives.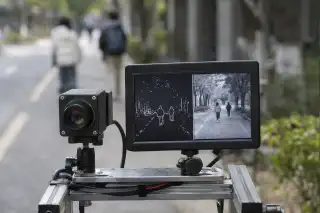
PASE separates agent skill procedures into editable code
The framework moves reusable procedures into executable programs to reduce repeated revisions to natural-language skill documents.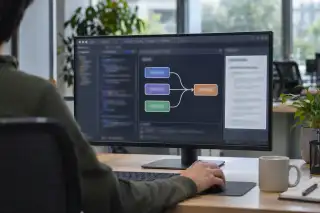
New York plans independent tests of AI models
New York's plan to scrutinise companies' claims externally should be read separately from the results those tests may produce.
Natural safety responses improve retention after training
Researchers propose NEST, a training approach that uses context-aware safety responses instead of formulaic refusals.
Higgsfield compares tools for video clips up to 30 seconds
The comparison covers clip length and credit costs, but includes no quality test using the same prompt.
Higgsfield ad guide leaves product checks to creators
Higgsfield’s guide puts prices in the editing stage and treats product accuracy as a separate check from AI labelling.
LEMMO extends signal analysis to detailed descriptions
The study broadens evaluation from signal classification to factual descriptions, with gains measured against comparisons published by the researchers.
Spacecraft AI memory scores differ after session restart
AstroMemBench researchers reported no clear advantage for memory systems over retrieval-augmented generation within the same session.
Linux reviewer steps down as AI patches add to workload
A report linking rising patch submissions with limited staffing underlined the need to assess AI coding tools through the review work they create.
ElevenLabs adds speaker labels to live transcription
The real-time speaker-labelling scores correct for transcription errors and cannot be compared directly with the recorded-audio results.
ChatGPT business hub tracks mentions and website clicks
OpenAI outlined business information management and visibility insights, while subsequent reporting identified website clicks as a specific measure.
ICLayout-Bench scores only circuit layouts that pass checks
A paper evaluating electrical performance and area reported substantial differences in model costs between configurations with similar scores.
Physics2Weight generates neural weights from physical laws
The study reports lower solution errors than conventional physics-informed neural networks, alongside limits in satisfying physical laws for nonlinear equations.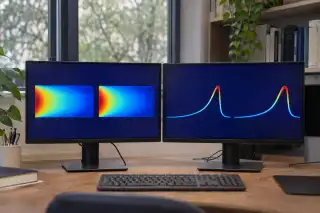
AI validation filters out harder language-model test items
Researchers said AI validation removed questions whose answers humans supported, raising language models' benchmark accuracy.
Binance warns iOS users of app isolation vulnerability
Developer release notes list tested iOS versions and installation requirements, while the researcher says the code is unrelated to jailbreaking.
Nvidia sets December release for GR00T 2 robot AI weights
The model predicts actions and environmental changes together, while datasets and tools have a separate release schedule from weights and robot-specific training methods.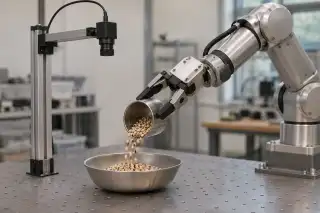
SK Intellix marks NAMUHX robot's first anniversary
NAMUHX's added functions include health consultation, while a senior care solution remains at the development stage.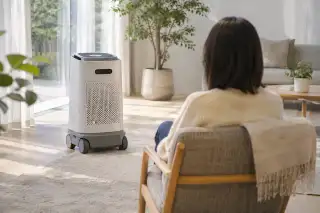
TimeOmni-o1 links language reasoning to forecasts
The researchers presented a two-way architecture that feeds language-model reasoning into time-series forecasting.
Real-time maths checks improve reported reasoning accuracy
A preprint reports higher symbolic maths accuracy alongside increased token use, while its abstract reports no independent replication.
Google launches benchmark for visual document tasks
MKA grades outputs in a shared execution environment while keeping its evaluation tasks private.
KAIST targets data management bottleneck in flash storage
The reported improvement focuses on moving and reorganising data so storage space can be reused.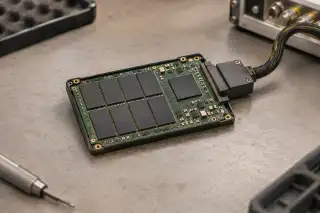
OmniReview offers benchmark for reviewer recommendations
Researcher profiles and staged evaluation aim to reflect real editorial workflows.
Infineon expects data centre power sales near €4 billion
TechXplore reported Infineon's expectation that AI data centre construction would continue despite opposition in the United States.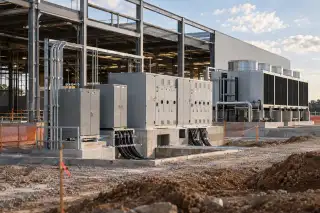
Kaggle winners put AI test design in focus
A challenge that asked developers to build their own evaluations shifted attention from model rankings to what the tests measured.
Medical AI shows gap between recall and evidence use
A Chinese-language benchmark reported lower scores for matching evidence and formulating recommendations than for identifying clinical information.
KTC plans digital medical product research event
Testing institutes, a hospital and a university consortium member will discuss research directions for the safety and reliability of AI-based digital medical products.
Daum plans AI short-drama service for next year's Q1
TechM reported that Daum plans to turn externally submitted scripts into AI-produced videos and pay ₩1 million for each script selected through a competition.
Naver shares Figma workflow for putting AI output into use
The presentation outlined how to express design intent in Figma and connect it to code.
Naver applies AI to commerce API checks, calls and support
Naver outlined how it used the same API specifications for automated checks, support answers and AI tool calls.
Artprice plans global subscriber access to search beta
Artprice plans a month of beta access before moving its commercial search service into higher subscription tiers and raising their prices.
Claude Fable 5.2 lowers input and output prices
Lower prices than the previous version leave data retention exceptions subject to each service’s terms.
Copilot CLI fixes parallel approvals and task stopping
The update changes approval handling for parallel requests and which shells stop with an agent, while Adobe’s Firefly plan review addresses control before execution.
OpenAI sets an end date for new fine-tuning jobs
New training and existing model use have separate cut-offs, while Werk emphasised the facts a model needs to receive.
Pinterest uses GLOC to share labels across image groups
Researchers reported better search quality and efficiency by generating descriptions for groups of similar images.Scientific code AI routes repairs by failure type
Targeted repairs and separate verification put token use and translation correctness under the same evaluation.Hybrid AI lacks evidence for 13.6% of police video events
Researchers reported speaker attribution errors and poorer performance across all tested systems on edited footage, long recordings and noisy audio.
PSI reports quantum proof using private Anthropic AI
PSI reported a proof and computer verification produced through its own research system using a private Anthropic model.Galaxy Corporation unveils book at polymath event
An event pairing robots with magic also introduced a book emphasising knowledge across several fields.
SPECTRA proposes restoring model refusals without retraining
Researchers report that transferring a base model’s refusal direction improves safety while preserving specialist knowledge.
MapHub reports results for personalised paper selection
The authors report paper-selection results from their own blind ratings, while the abstract reports no independent replication.TeViD compares two approaches to Turkish video fact-checking
TeViD combines fact-checking articles, translated material and synthetic examples to compare evidence retrieval with a fine-tuned model.
DeepBrain AI unites video creation and workplace avatars
AI Studios 5.0 combines tools for video production with conversational avatars for sales training, recruitment interviews and education.
JCMC proposes controls for persistent language model memory
The design checks predicted memory effects against observed results, but the paper reports no performance comparison with simpler retrieval methods.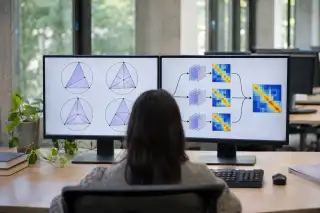
Israel AI chief proposes national control of AI stack
The proposal ties national sovereignty to direct ownership and management of energy, computing resources and AI models.
Spotify adds new voices to its AI DJ
Engadget reported that Spotify expanded its AI DJ voices and added the option to hear a DJ mix without commentary.
Qantas outsourcing plan affects 850 roles
The reported 850 roles describe the scope of an outsourcing deal, rather than new AI hiring.
Translation AI favours new meanings despite ignore orders
A controlled Mandarin-to-English experiment found that reliance on supplied word meanings varied with word frequency and sentence context.Luma pitches layered editing against Midjourney
Luma presented edits to individual image elements and links to video post-production as differences in its creative tools.Anthropic launches roadshow for proposed IPO
Anthropic set a proposed share price range, but its registration statement has not yet become effective.
AI recommends 180 previously unseen unregistered packages
The count checks AI-recommended package names against registries and tracks whether anyone registers them after a recommendation.Google DeepMind uses AI to verify Signal's core code
Google DeepMind said AI agents proved that executable code met security conditions reviewed by experts, with Lean checking each proof.JevGPT links evidence review with research planning
The dual-system design connects evidence processing to research planning, but the abstract gives no performance scores or costs for individual comparators.AI misinformation costs 3–169 times less to make than check
VEX-Bench assesses the burden of checking AI-generated misinformation across several dimensions.AI manufacturing models can run yet give wrong answers
Comparison with reference models exposed errors in the researchers' evaluation; the abstract reports no independent replication.DramaGrow reports accuracy gap between AI judging methods
The preprint compares repeated scoring with direct pairwise comparison and reports that evaluation procedures affect the accuracy of AI drama judges.Google Cloud introduces Gemini for healthcare in preview
The service is designed to prepare patient records and insurance paperwork, with read-only access through its Epic integration.Artprice share purchases signal shareholder support
The company's stated purpose for buying shares must be distinguished from the scale of forum reaction.
World Media Summit trailer sets out AI media challenges
A trailer combining live-action footage and AI-generated imagery puts journalistic principles and international cooperation on the agenda.
Two tools pair video downloads with 4K upscaling
Gigazine's review split video downloading and AI upscaling between VideoProc Converter AI and Aiarty Video Enhancer.Study raises video AI object-counting accuracy to 65.0%
The paper reports improved counting in synthetic videos alongside limits in real-video evaluation.Anthropic unveils models with performance and speed claims
Claims of better performance and speed require a separate assessment from the question of whether AI learns by itself.OpenAI control system blocks risky output within 35 seconds
The system revokes a problem task's execution permissions while keeping the model and other research running.
Linear merging lifts Turkish model's maths score to 0.63
Researchers reported that data quality mattered more than training volume in fine-tuning.MCGI adjusts vector search effort to data geometry
MCGI uses distances calculated during search to adjust search effort, with performance measured against DiskANN on the same index.Free model switches may change which files reach an AI
A DEV author warns that a review agent's input can change despite a normal response, but measurements of how often files are omitted and how much is lost remain unverified.
South Korea names KAIST, ETRI, LG AI Research for defence AI
The list of institutes is out, but the budget and detailed terms of support for small and venture defence firms have yet to be disclosed.
Extra layers give mixed gains in Vietnamese punctuation test
The preprint fixes training at eight epochs and does not report how rankings shift once architecture-specific tuning is added.OpenAI's Control Room tracks and can stop research workloads
OpenAI's introduction promises human control but does not say who stops a workload or by what standard.
RoleWalk embeds one million graph nodes on a single CPU core
The question for training-free structural embeddings is less speed than whether coordinates hold across different graphs.Luma targets Runway Gen-4.5's 10-second limit in rival pitch
The claim comes from a post promoting Luma's own products, which omits the maximum length and per-second price of its alternative, Ray 3.2.
Multilingual MARS agent trades retrievers for shell commands
The authors said MARS beat existing methods, but the abstract gives neither the accuracy gap nor the number of languages tested.
MSD declines Ingenia's IGT-302 glaucoma option as rights end
The glaucoma option under a separate agreement has ended, but the disclosure as reported gives no reason why MSD did not exercise it
Anthropic and Claude finish first vault 3D model in 34 hours
Anthropic's biology team reached an initial 3D model of a new vault particle form in 34 hours rather than weeks, AI Times reported, pointing to possible AI support in fields where scientists lack specialist experience.A YOLO extension reads runway lines for vision-based landing
The design backs up keypoints, which are prone to occlusion, with straight lines, but the abstract reports no real flight-test results.Nvidia highlights Korean manufacturers' physical AI in Seoul
Hyundai's factory digital twin and Korean robot projects featured at Nvidia's Seoul event, leaving real-world performance figures as the open issue.Skill at editing AI weights concentrates in a few new models
A structured-response task resisted every attempt, and success in one task family correlated poorly with success in others.Luma's commercial rights guide omits the usage terms for Ray
A guide comparing seven tools on commercial rights gives no plan or indemnification terms for Luma's own Ray.
Luma AI lists its own products first in LinkedIn tools guide
The guide does not give Ray 3.2's per-second price or say how Luma AI addresses LinkedIn's AI labelling rules.
DeepBrain AI brings chat-driven video agent to AI Studio 5.0
DeepBrain AI's release puts a proposed outline ahead of the finished video, while pricing and credit consumption remain open questionsGeoJeV trades 1.12 extra seconds for 5.32 points of accuracy
GeoJeV steers image search with probability distributions instead of generated text, but the abstract does not name the method behind its 7.8-fold speed comparison.MINE lifts Llama 3.1 8B inference speed 2.52x on RTX 4060 Ti
The researchers' figures come from a 2.1-bit EntQuant checkpoint of Llama 3.1 8B Instruct, and the speedup was 1.48 times on an RTX 5090.Khmer benchmark drops LLM judges but still needs LLM answers
The judge is gone from scoring, but LLMs still write the reference answers and the human check is one native speaker's ratings.Soongsil decoy servers block ARTEX AI tool in 60-server test
The test opponent was a tool disclosed as used in state-backed hacking, and public materials show no deployment on live production servers.Peer signals reduce LLM public accuracy by up to 47.8 points
The researchers wrote that multi-agent evaluations must measure whether agreement reflects private judgments, not only whether models reach it.Anthropic reports leak from 100-plus Korean company accounts
South Korea's privacy regulator is at the pre-review stage, and public documents do not state any link to a Railway disclosure or when the breach occurred.
Denoising audio before speaker embeddings raises error rates
The paper advises leaving input audio untouched and shrinking only the output vector, but its abstract gives no per-model error ratesShapley benchmark finds standard metrics differ on real data
The authors said standard metrics picked contradictory best methods on real data and that the way inputs are grouped mattered more than the choice of imputer.Anthropic reports data leak at over 100 Korean firm accounts
The PIPC, Korea's data protection regulator, said the case is at the preliminary review stage and the extent of the damage can be established after a formal investigation begins.20 Atari games expose vision AI's limits in following motion
The latest vision-language models often missed object motion and leaned on written history over new screens, a study found.Microsoft adds 25 Xbox games to new Windows PCs bought in US
PCs bought in South Korea fall outside the terms, and the two game lists in Microsoft's official document differ.
ML benchmark for chaotic three-body orbits publishes dataset
Stability prediction and long-horizon trajectory prediction differed in difficulty, the researchers wrote; the abstract gives no accuracy gaps between modelsNVIDIA names accuracy, safety as tests for commercial robots
NVIDIA held that reaching the level of autonomous driving does not alone meet the conditions for commercialisation, but its public event documents set no threshold figures.HITS signs KAIST drug research MOU for HyperLab AI programme
An AI platform company and a research group covering the full drug development cycle join one programmeSK-founded CSES unveils SEE SV to rate social impact with AI
SEE SV shifts evaluation from budgets and activity counts to change in beneficiaries' lives, while its models and data remain unconfirmed.KLEAR holds knowledge fixed to test Korean LLMs' application
The design aims to separate the causes of wrong answers that accuracy scores conceal, though the abstract names no evaluated models and gives no scores.GPT-6 Astra gains 22.9 points on OpenAI's life sciences test
The company-published gain compares OpenAI's own models on a test that OpenAI built with biotechnology company Ligo.NAVER Cloud's multimodal training throughput rises to 150.2%
A rebuilt vision encoder and rebalanced image load drove the gain, in a company-published result measured on one 30B model.
Elith and NVIDIA release 9M synthetic Japan finance personas
With 50 fields per record, the dataset targets financial AI development without real customer records, but the companies did not publish how closely it matches official statistics.2 weeks agoNov 05 – Nov 09
llama-modchip fits 284B DeepSeek model into 64GB RAM, no GPU
The file shrinks to 56.56GiB, but unpatched llama.cpp, Ollama and LM Studio cannot run it.InkQuest brings Gemini text games to a 2.9-inch e-ink screen
The creator's README labels battery life of about 20 hours as an estimate and lists no retail price for a finished device.Mosseri sees two more years of AI frustration, reports say
Two reports said Adam Mosseri also raised the idea of requiring AI accounts to label themselves, but public documents do not confirm who would be covered or when it would apply.
Gemini Omni 1.2 Flash adds 15-second clips, 30% cheaper 720p
Google published the 720p per-second price but has not disclosed upscaling costs or how its watermark relates to platform AI labelling rules.METR estimates 1.9x faster benchmark progress at Anthropic
METR attributed about 80% of the current acceleration to AI use, but Anthropic redacted a majority of the evidence behind that judgement.
OpenAI limits GPT-6 Cyber to approved security teams
OpenAI said the model helped find 81 Firefox vulnerabilities, but outside verification and a date for wider access have not been published.
Baidu opens ERNIE 5.5 Flash Base weights, but not for Korea
Baidu's pre-training-only base weights are free for commercial use up to a revenue threshold, but the licence does not cover the EU, the UK or South Korea.Crypto exchange Foblgate's AI security lab wins KOITA status
Foblgate plans a system that adds authentication or holds withdrawals on unusual activity, but its public documents give no rollout date.OpenAI joins Hacktron to find vulnerabilities in its systems
The work extends to testing connections with third-party services, but OpenAI has not disclosed the contract terms.More dreaming lifts Claude's wiki quiz score from 13% to 48%
In company-published figures, combining search with the wiki scored 61%, and Anthropic did not disclose the experiment's total cost.
Universities in Australia expand ChatGPT access and adopt AI
OpenAI gave preparation for an AI-enabled workforce as the aim, but its introductory text names no individual universities or student numbers.Luma lists its own product first in enterprise video roundup
Luma's post does not disclose the generation length, resolution or price per second of Ray 3.2.
Drex Max decision model scores 67.52 on Decision Index 0.4.1
The score and response times of the open model, which returns only a probability for each option, are the authors' own figures and have no independent replication.Apple's KeyNet cuts RAG search time by up to roughly 8 times
The research learns query patterns in advance to cut RAG search costs, and Apple's post does not give the pre-training time.462 in totalWritten by Gyeol HanRSS feed