01 / AI · Analysis
Shapley benchmark finds standard metrics differ on real data
The authors said standard metrics picked contradictory best methods on real data and that the way inputs are grouped mattered more than the choice of imputer.
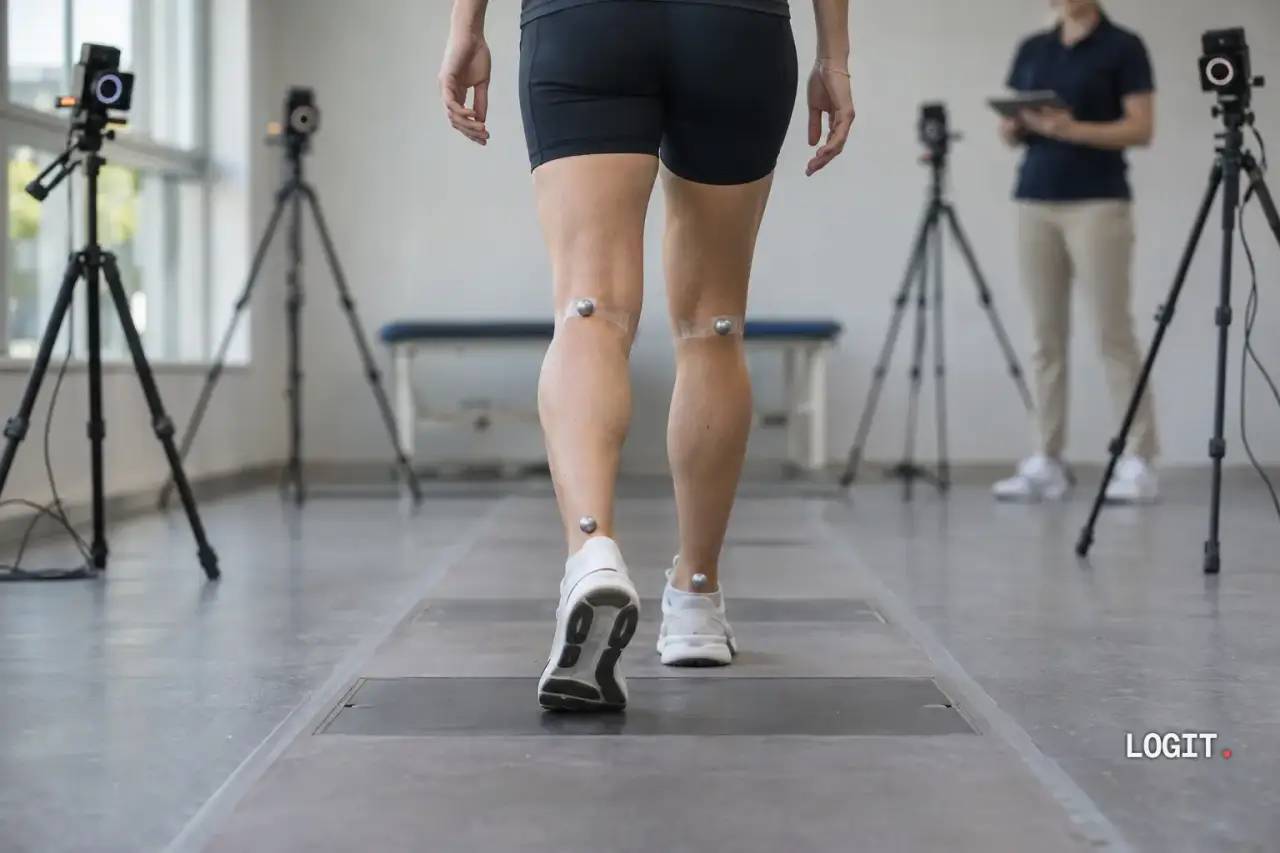
MotionBench-XAI, a paper published on arXiv on 9 Nov 2026, compared ten explanation methods on five synthetic and three real datasets. Its authors said how inputs are grouped matters more than how missing values are filled in.
The result matters because real data has no ground-truth explanations to check against, the authors noted. The standard metrics used in place of ground truth also reached conflicting conclusions.
According to the abstract, Shapley values are attributions that treat input features as players in a cooperative game and measure how the output changes as groups of players are removed. Three things must be decided before they are computed: what counts as a player, how absent players are replaced and how the game is evaluated. The paper's findings bear on those choices and on the metrics used to judge them.
Metrics that disagree on real data
On real data, the authors wrote, the standard proxy metrics, measures used in place of a direct check against ground truth, "select contradictory best methods". The methods the metrics ranked first contradicted one another. The abstract does not say which metric chose which method.
The real datasets cover clinical gait, electrocardiogram and audio. The abstract gives assessing the severity of Parkinson's disease from human motion as an example of a task that needs explanation. Practitioners need to know which joint or which time window drove the prediction.
Input grouping outweighs the choice of imputer
The authors wrote that the choice of how to group inputs into players matters more than the choice of imputer, a method that fills in absent inputs. Inputs are grouped across time, across space or across both. The abstract gives no figure for the size of that difference.
The benchmark, as published by the authors, comprises ten attribution methods, three player sets and three trained model architectures. Its five synthetic datasets have exact ground-truth Shapley values.
When generative imputers improve explanations
In the authors' published results, filling in absent inputs with a generative model improved explanations only when the conditional model was accurate. The abstract gives no threshold for the accuracy required.
The authors said they distilled the findings into practical guidance and provide an open-source pipeline. The abstract gives neither a repository address nor terms of use.
On the authors' published results alone, the evidence for choosing an explanation method on real data did not converge on a single metric.