01 / AI · Analysis
Forecast benchmark tests text that conflicts with trends
The study examined when text that contradicted historical trends increased forecast errors and how limiting forecast adjustments helped.
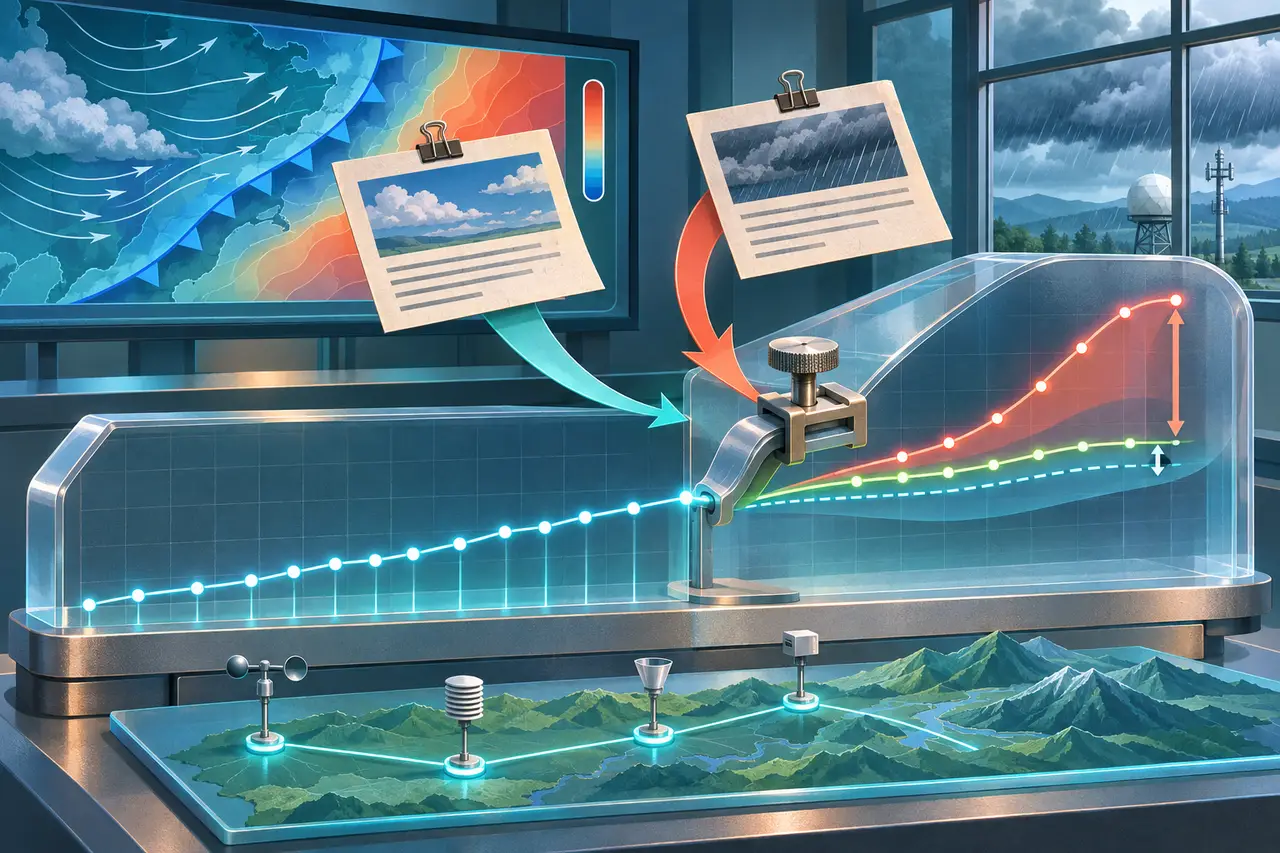
Researchers announced the release of a benchmark with 1,762 pairs of text and time-series records for evaluating forecasts when text agrees with, contradicts or leaves historical trends unspecified.
The paper examined how reliably models use external text alongside sensor records. Its results linked the usefulness of that text to whether its stated direction matched the historical trend.
The researchers evaluated both the selection and combination of text and the size of the resulting forecast adjustments. Their study covered the conditions for adding text to time series, records collected over time.
When text contradicts historical trends
The paper uses Aligned for text whose direction agrees with the historical trend and Conflicting for text that opposes it. A separate category covers text that states no direction.
The researchers compared two types of text against the same weather records: direct forecasts of temperature changes and descriptions of conditions such as winds and weather fronts. In the researchers’ published benchmark results, direct forecasts produced the lowest error for most models when they agreed with the historical trend.
When those direct forecasts contradicted the trend, they increased errors for most models, according to the researchers’ published results. The comparison was with forecasts generated without text.
Limits on forecast adjustments
The researchers combined only the magnitude and timing of changes stated in the direct forecasts with the text describing weather conditions. In their published benchmark results, this combination reduced errors and improved accuracy in predicting the direction of change for some models compared with either type of text alone.
The researchers attributed the increase in errors to excessively large forecast adjustments after breaking down the errors. They also evaluated a rule that limited those adjustments without additional training.
For the models affected by this trade-off, the limiting rule outperformed forecasts both with and without text, according to the researchers’ published benchmark results.
The study therefore identified the size of forecast adjustments as an evaluation concern alongside whether text was used at all. The abstract does not provide the specific formula for the rule that limits those adjustments.