Breaking01 / AI
Study compares voice AI for Spanish freight negotiations
The study compared errors in recognising spoken amounts and response delays measured from the listener's side.
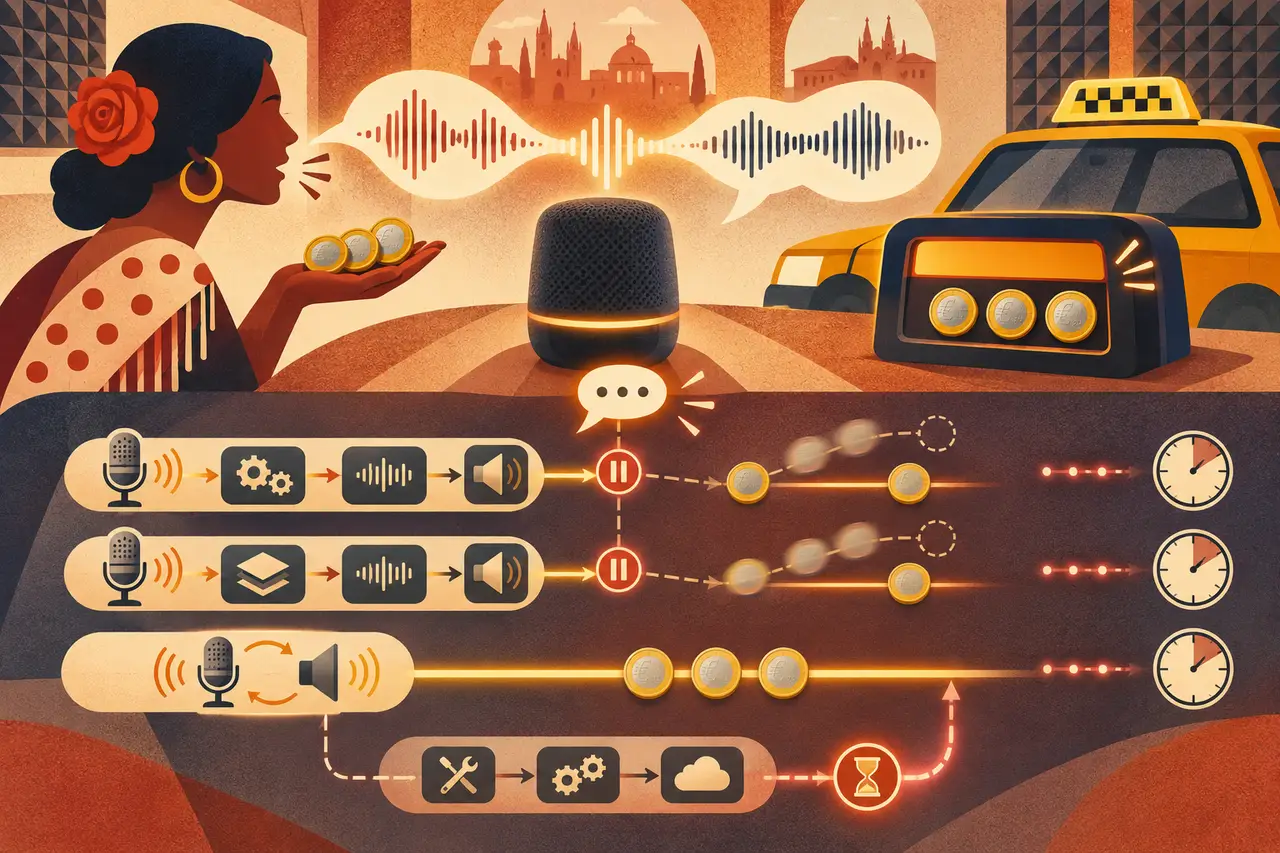
Researchers published a comparison of voice AI for Spanish freight-rate negotiations, testing each architecture in 77 calls without a telephone network.
The paper was published on arXiv on 17 Nov. It describes Pipecat and LiveKit as systems linking speech recognition, a language model and speech synthesis, while GPT-Live is an OpenAI speech model that listens and speaks without separate stages. The experiment played the same 47 recordings of one speaker to every system.
The paper reported median response delays measured from the listener's side of 2,616.0 ms for Pipecat, 3,090.0 ms for LiveKit and 2,444.8 ms for GPT-Live. The confidence interval for the difference between GPT-Live and Pipecat included zero, meaning the results did not establish a clear difference between them.
The paper reported error rates for recognising spoken amounts of 13.01% for Pipecat and 12.61% for LiveKit. GPT-Live's error rate was 2.86%.
The researchers reported that tool calls added 0.9–1.1 s of waiting time across all architectures. That exceeded the differences in response delay between the systems in the experiment.
With default settings, Pipecat and LiveKit stopped speaking at almost every brief acknowledgement from the other speaker, according to the paper. It also documented cases where an interruption was treated as a negotiation answer. The researchers specified that these descriptive counts were not statistically tested.
The researchers did not publish response-delay measurements taken over an actual telephone network.